A/B Testing: The Data Scientist‘s Secret Weapon for Optimization
Introduction
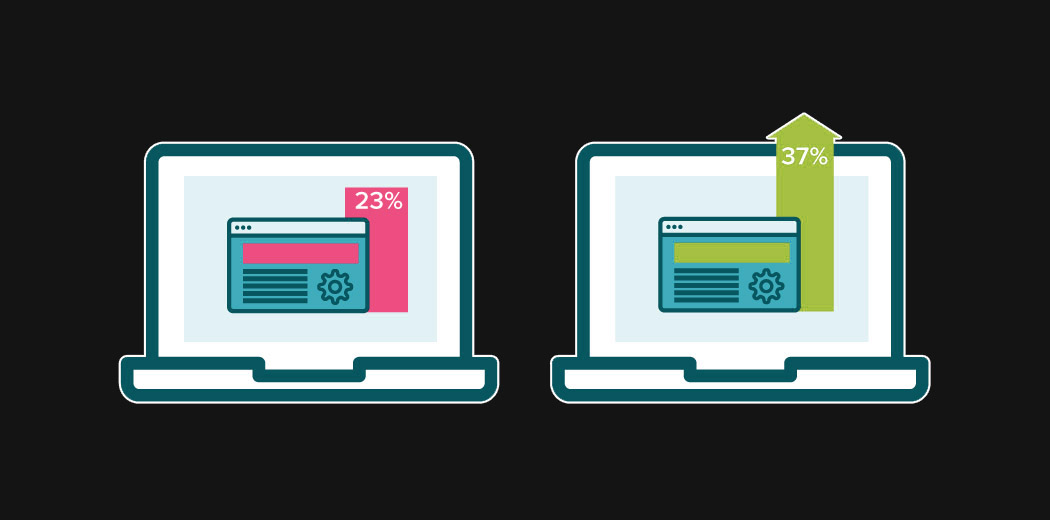
A/B testing, also known as split testing, is a powerful technique for data-driven decision making and optimization. By comparing two versions of an experience, A and B, you can determine which one performs better for a given metric. This allows you to iteratively improve your product, app, website, or marketing campaign based on real user behavior.
As a data scientist, A/B testing should be a core part of your toolbox. It‘s an empirical way to validate your hypotheses and let the data guide your recommendations. Rather than relying on intuition or guesswork, you can run controlled experiments to gather evidence and quantify the impact of changes.
A/B testing has a long history, with roots in statistical hypothesis testing dating back to the early 1900s. But it really took off in the digital age, with the rise of the internet and online advertising in the 1990s. Digital products made it much easier to randomly split traffic and measure user behavior at scale.
Today, A/B testing is ubiquitous among data-driven organizations. Tech giants like Google, Netflix, and Booking.com each run thousands of A/B tests per year on everything from UI changes to personalized recommendations. And tools like Optimizely and VWO have made A/B testing accessible even to smaller companies and non-technical marketers.
A recent study by Forrester found that 74% of companies now use some form of online testing to make decisions, with A/B testing being the most common method. And the impact is significant – Microsoft reported that using A/B testing has helped them generate an additional $1 billion in revenue over a 5 year period.
So how does A/B testing actually work under the hood? What are some key statistical concepts to understand? And how can data scientists leverage techniques like machine learning to take A/B testing to the next level? Let‘s dive in.
How A/B Testing Works
At its core, the A/B testing process involves the following steps:
-
Form a hypothesis – Start with a question you want to answer or an assumption you want to validate. Your hypothesis should clearly define your control (A) and test variant (B) and the expected impact on your metric. For example: "Adding testimonials to the homepage (B) will increase signups by 5% compared to the current homepage (A)."
-
Select your metric – Choose the key performance indicator (KPI) you want to optimize in your test. For an ecommerce site, this could be something like conversion rate, average order value, or revenue per visitor. Make sure your metric aligns with your high-level business goals and can be easily measured.
-
Calculate your sample size – Determine how many users you need in your test to detect a statistically significant difference between A and B. This depends on factors like your baseline metric value, minimum effect size, significance level, and statistical power. There are many online calculators to help determine the right sample size.
-
Split traffic between control and variant – Randomly assign a portion of your traffic to experience version A (control) and an equal portion to version B (variant). The randomization ensures the two groups are statistically equivalent and controls for other factors. Most A/B testing tools handle this split automatically.
-
Run the test and monitor – Let your test run for a sufficient period of time to collect data according to your predetermined sample size. Monitor the results along the way to check for any drastic negative changes that would require stopping the test early (but resist the urge to declare a winner prematurely).
-
Analyze the results – Once the test concludes, compare the performance of A vs B for your primary metric. Did B outperform A as you hypothesized? Segment the results by key user attributes to uncover deeper insights. Most importantly, determine if the difference between A and B is statistically significant using techniques like hypothesis testing.
Statistical significance is a critical concept in A/B testing. Just because variant B had a higher conversion rate than control A doesn‘t necessarily mean it‘s better. The difference could be due to random chance, especially with a small sample size.
To have confidence that your results reflect a true difference and would generalize to all users, you need to assess the statistical significance. This involves calculating a p-value, which quantifies the probability of observing your results if there was actually no difference between the versions (the null hypothesis).
The most common significance threshold is a p-value less than 0.05, corresponding to a 95% confidence level. If your p-value is below 0.05, you can reject the null hypothesis and conclude there‘s a statistically significant difference between A and B.
Another way to report the results is with a confidence interval. A 95% confidence interval represents the range of values that you can be 95% confident contains the true difference between A and B. If the confidence interval doesn‘t include 0 (i.e. the entire range is positive or negative), that also indicates statistical significance.
A/B Testing Statistics Explained
Here‘s a closer look at some key statistical concepts for A/B testing:
Hypothesis Testing
A/B testing is a form of two-sample hypothesis testing. Your null hypothesis (H0) is usually that there‘s no difference between version A and B. Your alternative hypothesis (H1) is that B is different from A (two-sided test) or that B is greater/less than A (one-sided test).
After running the test, you‘ll either reject the null hypothesis (and conclude there‘s a significant difference) or fail to reject the null hypothesis (and conclude there‘s not enough evidence of a difference).
Type I and II Errors
There are two types of errors that can occur in hypothesis testing:
-
Type I error (false positive) – Rejecting the null hypothesis when it‘s actually true. This means concluding there‘s a difference between A and B when there‘s really not. The probability of a type I error is equal to your significance level (α), commonly 0.05.
-
Type II error (false negative) – Failing to reject the null hypothesis when it‘s actually false. This means concluding there‘s no difference when there actually is one. The probability of a type II error is denoted by β and is related to the statistical power (1-β).
Statistical Power
Statistical power is the probability of detecting a statistically significant difference when there really is one (i.e. correctly rejecting the null hypothesis). It depends on your sample size, effect size, and significance level.
Larger sample sizes and effect sizes increase statistical power, while a lower significance level decreases power. A common threshold is 80% power, meaning an 80% chance of detecting a true difference. This corresponds to a 20% probability of a type II error (β=0.2).
Z-Test vs T-Test
There are two main statistical tests used in A/B testing: the Z-test and T-test. Both compare whether the means of two samples are significantly different.
The Z-test is used when the sample size is large (typically n > 30) and population variance is known. The T-test is used when the sample size is small or population variance is unknown. It‘s generally recommended to use a T-test for most A/B tests, as population variance is rarely known in practice.
The test statistic (Z or T) is calculated based on the difference between sample means, variability of the data, and sample size. It‘s then compared to a critical value from the standard normal or T distribution to determine the p-value.
Multivariate Testing
While A/B testing compares two versions, multivariate testing compares multiple factors simultaneously. Instead of a single control and treatment, you create multiple variants by combining different versions of each factor.
For example, suppose you want to test two versions of a headline (A, B), two images (C, D), and two CTAs (E, F) on a landing page. A multivariate test would create 8 variants (ACE, ACF, ADE, ADF, BCE, BCF, BDE, BDF) and compare all of them to find the best performing combination.
Multivariate tests are useful for understanding interaction effects between variables, but they require much larger sample sizes. They‘re typically used when you have multiple elements you want to optimize and enough traffic to reach significance.
Advanced A/B Testing with Machine Learning
While traditional A/B testing is a powerful tool, it has some limitations. Tests can take a long time to reach significance, and you can only test a small number of variants at a time. This is where machine learning comes in.
Machine learning algorithms can analyze large amounts of data to identify patterns and make predictions. In the context of A/B testing, this means ML can help select the best variant for each individual user based on their attributes and behavior. Rather than showing the same variant to all users, you can dynamically allocate traffic to maximize total conversions or revenue.
Two popular ML techniques for A/B testing are multi-armed bandit algorithms and Bayesian optimization:
Multi-Armed Bandits
Multi-armed bandit (MAB) algorithms are a type of reinforcement learning used for optimization over time. The name comes from a hypothetical scenario where a gambler has to choose which slot machine (one-armed bandit) to play to maximize their winnings.
In an A/B test context, each variant is like a slot machine, and the reward is a conversion or other positive event. The goal is to allocate traffic to the best performing variant, while still exploring other variants that could be even better.
MAB algorithms balance the tradeoff between exploiting the current best variant and exploring others. Over time, more traffic is allocated to the best variant, but some traffic is still reserved for exploring the other arms. This allows the algorithm to adaptively learn and optimize for long-term performance.
There are many MAB algorithms (epsilon-greedy, UCB, Thompson sampling), but the basic idea is to use the observed performance so far (e.g. conversion rates) to estimate the value of each variant. The algorithm then allocates the next user to the variant with the highest estimated value, with some randomness for exploration.
MABs often outperform traditional fixed-horizon A/B tests in terms of total conversions or revenue. Since they adapt in real-time, they can quickly shift traffic to the best variant without waiting for a fixed sample size. And by constantly exploring, they can identify new top performers over time as user preferences change.
Bayesian Optimization
Bayesian optimization is another sequential optimization technique that‘s well-suited for A/B testing. It works by building a probabilistic model of the objective function (e.g. conversion rate) based on past observations. It then uses this model to select the next variant to test that will maximize the expected improvement (EI) or expected value (EV) over the current best.
The key idea is to balance exploration and exploitation by testing variants that are most likely to perform well given the current model (exploitation) but also have high uncertainty (exploration). As more data is collected, the model becomes more confident and shifts from exploration to exploitation.
Bayesian optimization is particularly useful when you have a large number of variants to test and each observation is expensive (e.g. measuring long-term revenue). It can often find the best variant faster than traditional A/B testing by being more strategic about which variants to allocate traffic to.
The downside of Bayesian optimization is that it can be more computationally intensive and requires careful selection of the prior distribution and acquisition function. But with the rise of powerful ML libraries like GPyOpt and BoTorch, it‘s becoming increasingly accessible to data scientists.
Conclusion
A/B testing is a cornerstone of data-driven optimization and should be a key part of any data scientist‘s toolkit. By running controlled experiments and using statistical analysis, you can empirically test hypotheses and identify the best performing variants for your KPIs.
However, A/B testing is both a science and an art. It requires a deep understanding of statistics and experimental design to ensure valid and reliable results. But it also takes creativity and domain expertise to generate impactful test ideas and interpret the results in a business context.
As a data scientist, you can leverage machine learning techniques to take your A/B testing to the next level. Multi-armed bandits and Bayesian optimization can help you adapt to changing user preferences and find the optimal variant faster. And with the rapid advancements in AI and automation, the future of A/B testing is looking brighter than ever.
So whether you‘re a beginner or an expert, I encourage you to embrace A/B testing and make it a habit in your data science work. Start with simple tests to build momentum, then gradually expand to more complex experiments. Stay curious, question your assumptions, and let the data guide you. The rewards of a culture of experimentation are well worth the effort.