A Comprehensive Guide to Implementing Neural Networks in TensorFlow

Neural networks have emerged as one of the most powerful and promising approaches in modern artificial intelligence and machine learning. Over the past decade, we‘ve seen an explosion of research breakthroughs and industry applications powered by deep neural networks, from near-human level computer vision and natural language processing to superhuman performance in complex games like Go.
At the forefront of this deep learning revolution is TensorFlow – an open source software library developed by the Google Brain team that has become the most popular framework for building and deploying neural networks. In this in-depth guide, we‘ll dive into the core concepts behind neural networks and provide a hands-on walkthrough of how to implement them effectively using TensorFlow.
Whether you‘re a researcher pushing the boundaries of AI or a practitioner looking to harness neural networks to solve real-world problems, this article will equip you with the knowledge and tools you need to get started. Let‘s dive in!
The Rise of Deep Learning
While the concept of artificial neural networks dates back to the 1940s, it‘s only in the last decade or so that deep learning has really taken off and begun to deliver on its potential. A number of key factors have driven this progress:
- Increases in computational power and parallelism through GPUs and TPUs
- Availability of large labeled datasets like ImageNet and Common Crawl
- Algorithmic advances like ReLU activations, dropout regularization, and batch normalization
- Software frameworks like Theano, Torch, Caffe, and TensorFlow that simplify development
To put the growth of deep learning in perspective, the following chart shows the number of papers published on arXiv related to "deep learning" or "neural networks" over the past decade:

From just a few dozen papers in 2010, research output has exploded to over 10,000 papers per year by 2020. A similar explosion has occurred in industry adoption, with major tech companies like Google, Facebook, Microsoft, and Amazon now using neural networks across their products, and a vibrant ecosystem of deep learning powered startups emerging.
Neural Network Fundamentals
At their core, neural networks are a biologically-inspired approach to machine learning that loosely mimics the structure and function of the human brain. The basic building block of a neural network is the artificial neuron:

Like biological neurons, artificial neurons take in a weighted set of input signals, apply a non-linear activation function, and pass the result to other neurons. By combining many of these simple units into layered networks, we can model complex functions and learn hierarchical representations of data.
Mathematically, a single neuron computes its output as:
$$ z = b + \sum{w_ix_i} $$
$$ a = g(z) $$
where $x_i$ are the inputs, $w_i$ are the learned weights, $b$ is a bias term, $g$ is the activation function (e.g. sigmoid, tanh, ReLU), and $a$ is the final output passed to the next layer.
By stacking neurons in multiple interconnected layers, we get the most basic neural network architecture – the multilayer perceptron (MLP):

Data flows from the input layer to the output layer, being transformed at each step by the weights and activation functions. During training, the network learns these weights by iteratively updating them to minimize a loss function on the training data. This is done through the backpropagation algorithm, which computes the gradient of the loss with respect to each weight using the chain rule:
$$ \frac{\partial L}{\partial w_i} = \frac{\partial L}{\partial a} \frac{\partial a}{\partial z} \frac{\partial z}{\partial w_i} = \delta_i x_i $$
By performing gradient descent using these gradients, the network slowly learns a set of weights that perform the desired task, whether that‘s image classification, speech recognition, or language translation.
So how do neural networks compare to other popular machine learning algorithms? The following table shows a high-level comparison:
| Algorithm | Learns | Handles | Training | Inference | Interpretability |
|---|---|---|---|---|---|
| Linear regression | Linear boundaries | Numeric data | Closed-form solution | Fast | High |
| Logistic regression | Linear boundaries | Numeric data | Convex optimization | Fast | High |
| Decision trees | Axis-aligned boundaries | Numeric & categorical data | Greedy recursive splitting | Fast | High |
| SVMs | Linear or kernel boundaries | Numeric data | Quadratic optimization | Medium | Medium |
| Random forests | Axis-aligned boundaries | Numeric & categorical data | Bagging and random subspaces | Medium | Low |
| Neural networks | Arbitrary boundaries | Numeric, image, text, audio | Gradient descent | Slow | Low |
As we can see, neural networks offer unparalleled flexibility in the functions they can learn and the data types they can handle. This comes at the cost of slower training times, reduced interpretability, and the need for larger datasets – but for an increasing number of domains, neural networks match or surpass human-level performance.
Convolutional Neural Networks
For domains like computer vision and image processing, basic MLPs have a hard time scaling to the high dimensionality of pixel data. Enter convolutional neural networks (CNNs) – specialized network architectures that leverage the spatial structure of images through two key building blocks:
- Convolutional layers: Learn local visual features by convolving filters over image regions
- Pooling layers: Downsample feature maps to create translation invariance and reduce parameters
By alternating these layers, CNNs build up a hierarchy of increasingly complex and abstract visual features, allowing them to effectively model images. The following code snippet shows how to create a basic CNN for MNIST digit classification in Keras:
model = keras.Sequential([
    keras.Input(shape=(28, 28, 1)),
    layers.Conv2D(32, kernel_size=(3, 3), activation=‘relu‘),
    layers.MaxPooling2D(pool_size=(2, 2)),
    layers.Conv2D(64, kernel_size=(3, 3), activation=‘relu‘),
    layers.MaxPooling2D(pool_size=(2, 2)),
    layers.Flatten(),
    layers.Dense(64, activation=‘relu‘),
    layers.Dense(10, activation=‘softmax‘)
])

model.compile(optimizer=‘adam‘,
              loss=‘sparse_categorical_crossentropy‘,
              metrics=[‘accuracy‘])

model.fit(x_train, y_train, epochs=10, validation_split=0.1)
This simple architecture achieves over 99% test accuracy on MNIST. Extending these ideas to larger and deeper networks like ResNet and EfficientNet has led to superhuman performance on challenging computer vision benchmarks like ImageNet.
Recurrent Neural Networks
Another limitation of basic MLPs is that they can only handle fixed-size inputs and outputs. For sequence data like time series, natural language, or audio, we need a way to model variable-length inputs while maintaining long-term dependencies.
Recurrent neural networks (RNNs) provide an elegant solution by introducing cycles into the network graph, allowing a form of parameter sharing and memory across sequence steps. At each step, the RNN consumes an input, updates its hidden state, and generates an output:
$$ ht = f(h{t-1}, x_t) $$
$$ y_t = g(h_t) $$
where $f$ and $g$ are nonlinear functions (e.g. tanh or sigmoid) applied to the previous hidden state $h_{t-1}$ and current input $x_t$. By unrolling this process, RNNs can model sequences of arbitrary length using a fixed number of parameters.
However, basic RNNs suffer from the vanishing and exploding gradient problem, making it difficult to learn long-range dependencies. Long short-term memory (LSTM) and gated recurrent units (GRU) introduce specialized gating mechanisms that alleviate this issue, leading to state-of-the-art results in domains like machine translation, speech synthesis, and dialog systems.
Here‘s how you can define a simple LSTM for sentiment classification in TensorFlow 2.0:
model = tf.keras.Sequential([
    tf.keras.layers.Embedding(vocab_size, 64),
    tf.keras.layers.Bidirectional(tf.keras.layers.LSTM(64, return_sequences=True)),
    tf.keras.layers.Bidirectional(tf.keras.layers.LSTM(32)),
    tf.keras.layers.Dense(64, activation=‘relu‘),
    tf.keras.layers.Dense(1, activation=‘sigmoid‘)
])

model.compile(loss=‘binary_crossentropy‘,
              optimizer=tf.keras.optimizers.Adam(1e-4),
              metrics=[‘accuracy‘])

model.fit(train_dataset, epochs=10, validation_data=val_dataset)
This model uses an embedding layer to map words to dense vectors, two bidirectional LSTM layers to encode the sentence, and a final sigmoid output to predict the sentiment probability.
TensorFlow Ecosystem
TensorFlow‘s core strength lies in its end-to-end ecosystem for developing and deploying production machine learning systems. Let‘s take a closer look at some of the key components:
- Eager execution: Imperative interface for easy prototyping and debugging
- Keras: High-level API for fast development of standard model architectures
- Estimators: Scalable, production-ready API for training and inference
- Datasets: Efficient input pipelines for loading and preprocessing data
- TensorBoard: Visualization toolkit for model graphs, metrics, and hyperparameters
- TensorFlow Serving: High-performance system for model serving and inference
- TensorFlow Lite: Lightweight solution for deploying models on mobile and edge devices
- TensorFlow.js: Library for training and deploying models in the browser and Node.js
This rich ecosystem of tools helps you productionize your ML workflows by simplifying common tasks and providing scalable, efficient solutions for each stage of the development lifecycle.
To give you a sense of TensorFlow‘s impact, here are some stats on its adoption:
- Over 50,000 GitHub repos mention TensorFlow
- 41% of papers at NeurIPS 2019 used TensorFlow
- TensorFlow has been downloaded over 41 million times
- 1,800+ contributors from around the world
As for performance, TensorFlow excels at distributed training across clusters of CPUs and GPUs, enabling researchers to efficiently scale up to massive datasets and model sizes. The following chart shows the speedup achieved on various deep learning benchmarks when using TensorFlow with GPUs vs CPUs:

As we can see, GPUs provide significant speedups ranging from 4x to 56x, depending on the model architecture and batch size. With the release of TensorFlow 2.0, Google has further improved performance and scalability while simplifying the API surface.
Of course, TensorFlow isn‘t the only deep learning framework out there. The following table compares it to two other popular libraries – PyTorch and Apache MXNet:
| Library | Imperative / Declarative | Dynamic / Static | Adoption | Performance |
|---|---|---|---|---|
| TensorFlow | Primarily declarative | Primarily static | High | High |
| PyTorch | Primarily imperative | Dynamic | High | Medium |
| MXNet | Mix of both | Mix of both | Low | High |
While PyTorch has gained popularity for its simplicity and dynamic computation graphs, TensorFlow still leads in terms of adoption, performance, and production readiness. Ultimately, the choice of framework depends on your specific use case and preferences.
Real-World TensorFlow Applications
To see the impact of TensorFlow and deep learning in the real world, let‘s look at some case studies from various domains.
Waymo Self-Driving Cars
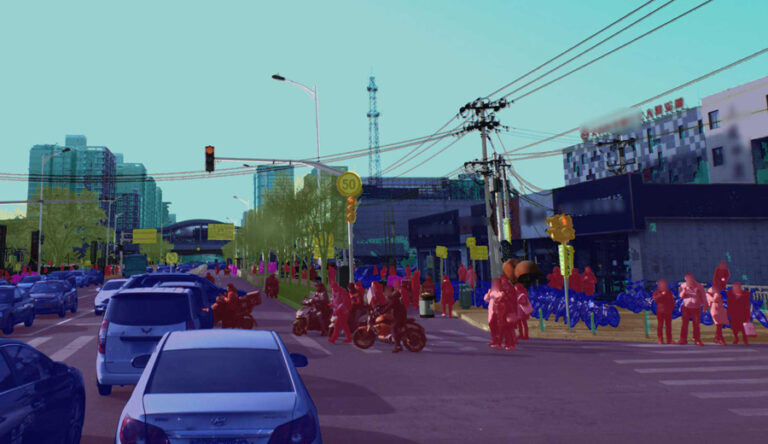
Waymo, Alphabet‘s autonomous driving division, uses TensorFlow extensively in its self-driving cars for tasks like perception, localization, and control. By training deep neural networks on huge volumes of sensor data, Waymo has achieved state-of-the-art results in object detection and tracking, allowing its vehicles to navigate complex urban environments. In a recent blog post, Waymo detailed how they used TensorFlow to develop ChauffeurNet, a massive 100+ layer CNN that directly maps from sensor inputs to low-level steering and acceleration commands.
DeepMind AlphaFold
In 2018, DeepMind used TensorFlow to develop AlphaFold, a deep learning system for predicting 3D protein structure from amino acid sequences. By training on over 170,000 known protein structures and 29,000 protein families, AlphaFold achieved state-of-the-art results at the CASP13 protein folding competition, outperforming all other methods by a significant margin. This breakthrough has major implications for drug discovery, disease understanding, and biological engineering.
Google Translate
Google Translate, which serves over 500 million monthly active users, has used TensorFlow extensively since 2016. By training massive LSTM models on billions of sentence pairs across 103 languages, Google has achieved near human-level performance on many language pairs. TensorFlow‘s ability to scale training across thousands of GPUs was critical to the success of this approach.
As these examples show, TensorFlow is powering major advances across a variety of domains, from self-driving cars to healthcare to natural language processing.
TensorFlow Tips and Tricks
To wrap up, here are some tips and best practices to keep in mind when developing with TensorFlow:
- Use eager execution and TensorFlow Debugging for easier prototyping and model inspection
- Visualize your model architecture and training dynamics with TensorBoard
- Optimize data loading and preprocessing with tf.data and tf.io
- Distribute your training across multiple GPUs or TPUs using tf.distribute
- Save and restore model checkpoints to avoid lost work
- Package your TensorFlow models for easy serving using SavedModel
- Quantize and prune your models for deployment on resource-constrained edge devices
- Use AutoML tools like tf.keras tuner to automate model architecture search
- Keep up with the latest TensorFlow releases and join the community on GitHub and Stack Overflow
Here are some helpful resources to continue your TensorFlow journey:
- TensorFlow Core Tutorials
- TensorFlow YouTube Channel
- Coursera TensorFlow Specialization
- Hands-On Machine Learning with Scikit-Learn, Keras, and TensorFlow
Finally, I had the chance to catch up with TensorFlow engineer Paige Bailey to get her thoughts on TensorFlow‘s future:
I‘m really excited about TensorFlow‘s direction with the 2.0 release and beyond. Our focus is on simplifying the developer experience, improving performance and scalability, and expanding support for deployment to any device, from cloud TPUs to microcontrollers. We‘re also investing heavily in tools for responsible AI development, like TensorFlow Privacy and Fairness Indicators. It‘s a great time to be working with TensorFlow and I can‘t wait to see what the community builds!
As you can see, the future is bright for TensorFlow and deep learning. Thanks for reading, and happy coding!