A Deep Dive into Binary Search Algorithms: Insights from an AI/ML Perspective
Introduction
Searching is a fundamental operation in computer science and a key component of many artificial intelligence (AI) and machine learning (ML) algorithms. Whether it‘s searching for the best model parameters, the most relevant features, or the nearest neighbors in a dataset, efficient search algorithms are crucial for performance and scalability.
One of the most well-known and widely used search algorithms is the binary search algorithm. Binary search is a classic algorithm that has stood the test of time due to its simplicity, efficiency, and wide range of applications. In this deep dive, we‘ll explore binary search from an AI/ML perspective, uncovering its inner workings, analyzing its performance, and discussing its potential applications and limitations in AI/ML.
What is Binary Search?
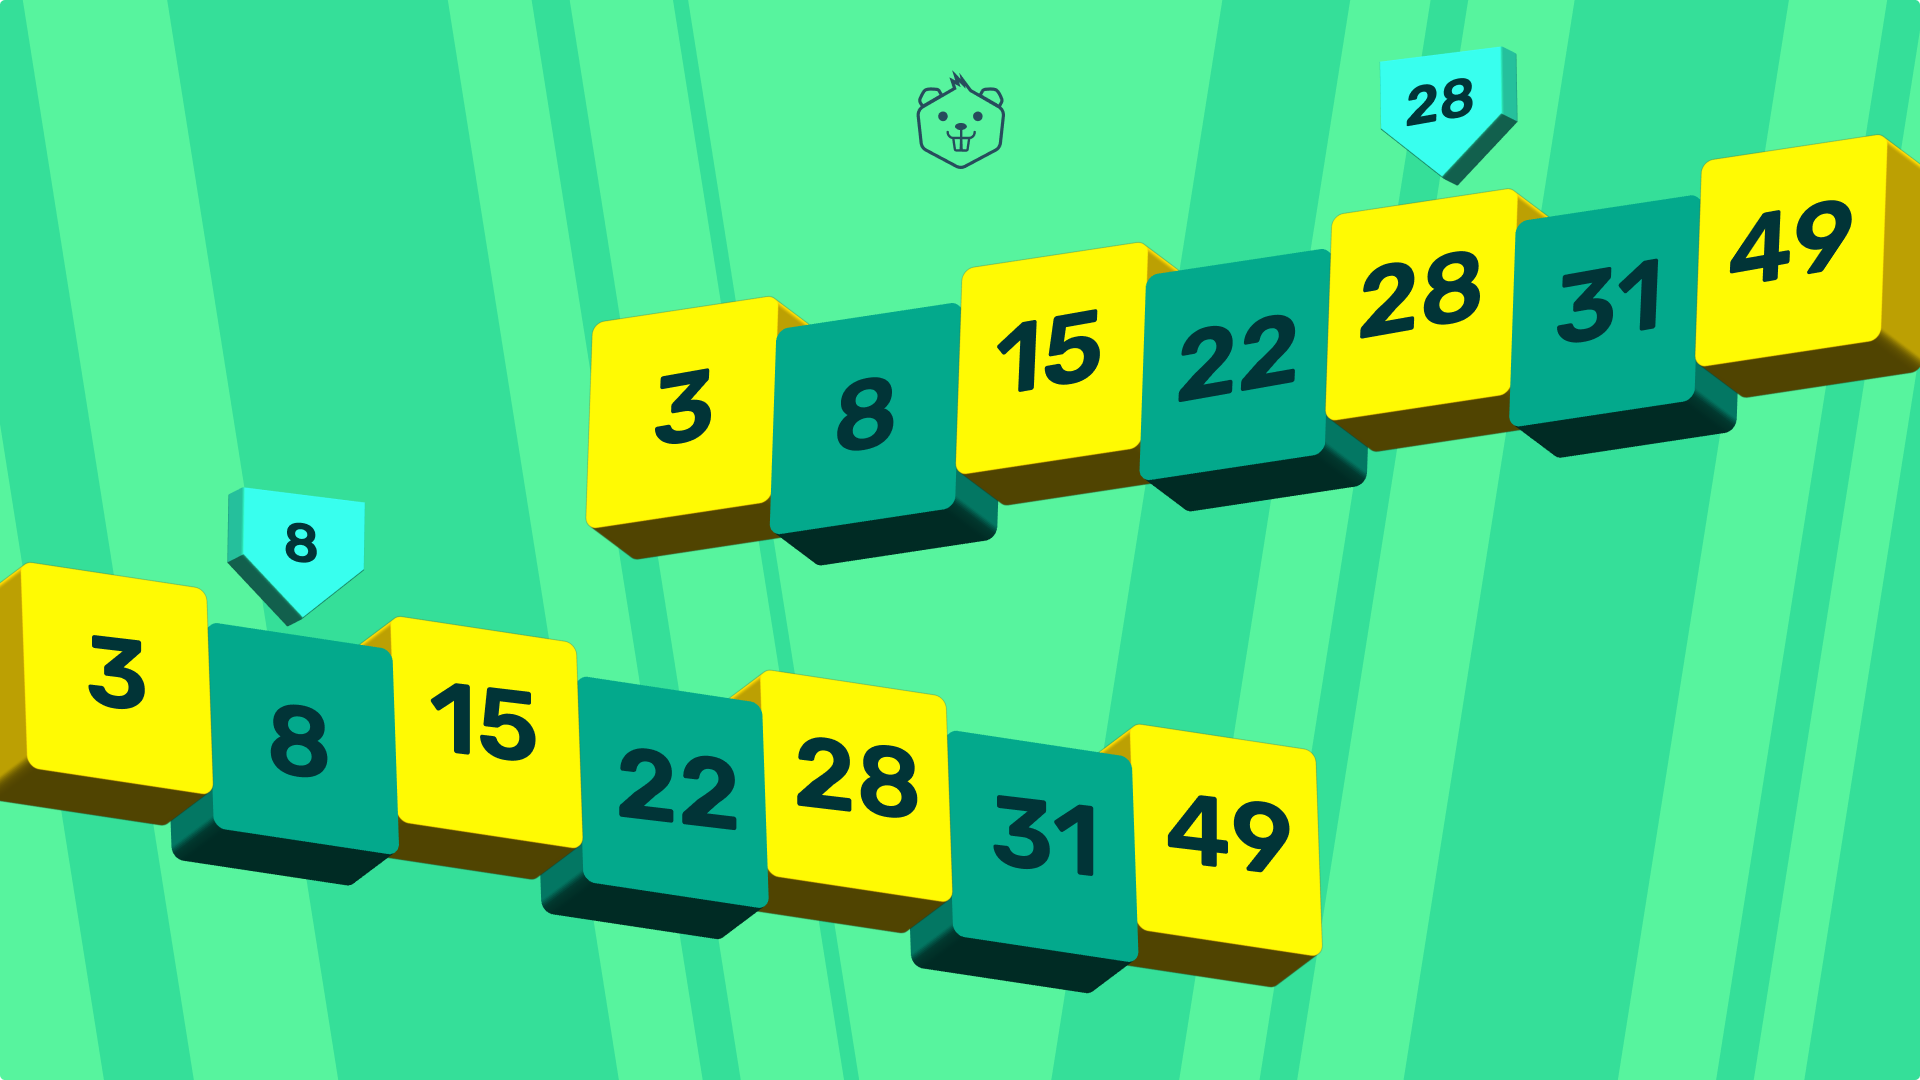
At its core, binary search is a divide-and-conquer algorithm that efficiently searches for a target value within a sorted array or list. The key idea behind binary search is to repeatedly divide the search space in half until the target value is found or the search space is exhausted.
Here‘s a step-by-step breakdown of how binary search works:
- Begin with a sorted array and a target value to search for.
- Compare the target value with the middle element of the array.
- If the target value matches the middle element, return the index of the middle element.
- If the target value is less than the middle element, recursively search the left half of the array.
- If the target value is greater than the middle element, recursively search the right half of the array.
- Repeat step 2 until the target value is found or the search space is exhausted.
The power of binary search lies in its ability to reduce the search space by half at each iteration. This results in a time complexity of O(log n), where n is the size of the input array. In contrast, a linear search, which examines each element sequentially, has a time complexity of O(n).
To illustrate the efficiency of binary search, let‘s consider an example. Suppose we have a sorted array of 1 million elements and we want to search for a specific value. With linear search, we may need to examine all 1 million elements in the worst case. However, with binary search, we can find the target value in at most 20 comparisons (log2(1,000,000) ≈ 20). This dramatic reduction in the number of operations highlights the power of binary search.
Binary Search and Information Theory
Interestingly, binary search has a close connection to information theory and the concept of bits. In information theory, a bit is the fundamental unit of information, representing a choice between two alternatives (usually 0 and 1).
When we perform binary search, we are essentially asking a series of yes/no questions to narrow down the search space. Each comparison in binary search can be seen as a bit of information that helps us make a decision. By repeatedly dividing the search space in half, we are effectively encoding the position of the target value using a sequence of bits.
This connection to information theory provides a deeper understanding of why binary search is so efficient. By leveraging the power of bits and making optimal decisions at each step, binary search minimizes the number of comparisons needed to find the target value.
Binary Search in AI and ML
While binary search is a general-purpose algorithm, it finds many applications in the field of AI and ML. Let‘s explore a few areas where binary search can be employed effectively.
Efficient Searching in Large Datasets
In AI and ML, we often deal with large datasets containing millions or even billions of data points. Searching for specific data points or nearest neighbors in such datasets can be computationally expensive. Binary search can be used to efficiently search through sorted datasets, enabling faster data retrieval and processing.
For example, consider a recommendation system that needs to find the most similar items to a given item based on a similarity metric. By sorting the items based on their similarity scores and applying binary search, we can quickly identify the top-k most similar items without having to compare against every item in the dataset.
Feature Selection
Feature selection is the process of selecting a subset of relevant features from a larger set of features to improve model performance and reduce computational complexity. Binary search can be used as a feature selection technique by treating the number of features as the search space.
Here‘s how it can work:
- Sort the features based on their relevance scores or importance measures.
- Perform binary search to find the optimal number of features that maximizes the model‘s performance metric (e.g., accuracy, F1 score).
- Start with half of the features and evaluate the model‘s performance.
- If the performance improves, recursively search the upper half of the features.
- If the performance degrades, recursively search the lower half of the features.
- Repeat step 2 until the optimal number of features is found.
By using binary search, we can efficiently explore the feature space and find the most informative features without exhaustively evaluating all possible subsets.
Hyperparameter Tuning
Hyperparameter tuning is the process of finding the optimal set of hyperparameters for a machine learning model to achieve the best performance. Hyperparameters are the settings that control the model‘s behavior, such as learning rate, regularization strength, or number of hidden layers in a neural network.
Binary search can be applied to hyperparameter tuning by treating the range of hyperparameter values as the search space. For each hyperparameter, we can define a range of possible values and perform binary search to find the optimal value that maximizes the model‘s performance metric.
Here‘s an example of how binary search can be used for tuning the learning rate of a model:
- Define the range of learning rates to search (e.g., [0.0001, 0.1]).
- Perform binary search to find the optimal learning rate:
- Start with the middle value of the range (e.g., 0.05) and evaluate the model‘s performance.
- If the performance improves, recursively search the upper half of the range.
- If the performance degrades, recursively search the lower half of the range.
- Repeat step 2 until the optimal learning rate is found.
By using binary search, we can efficiently explore the hyperparameter space and find the best settings for our model, reducing the computational overhead compared to exhaustive search or random search.
Binary Search vs. Other Search Algorithms
While binary search is a powerful and efficient algorithm, it‘s important to understand its limitations and compare it with other search algorithms used in AI and ML.
Breadth-First Search (BFS) and Depth-First Search (DFS)
Breadth-first search (BFS) and depth-first search (DFS) are two fundamental graph traversal algorithms used in AI for exploring search spaces and finding paths or solutions. BFS explores all the neighboring nodes at the current depth before moving to the next depth level, while DFS explores as far as possible along each branch before backtracking.
Compared to binary search, BFS and DFS are more suitable for searching in unordered and unstructured search spaces, such as graphs or trees. They can handle non-linear search spaces and find paths or solutions that binary search cannot.
However, BFS and DFS have higher time and space complexity compared to binary search. BFS has a time complexity of O(V + E), where V is the number of vertices and E is the number of edges in the graph, and a space complexity of O(V) to store the queue. DFS has a time complexity of O(V + E) and a space complexity of O(V) to store the stack.
Heuristic Search Algorithms
Heuristic search algorithms, such as A* search, best-first search, and beam search, use heuristic functions to guide the search towards the most promising solutions. These algorithms are commonly used in AI for pathfinding, game playing, and optimization problems.
Compared to binary search, heuristic search algorithms can efficiently explore large search spaces by using domain-specific knowledge to estimate the cost or distance to the goal state. They can find optimal or near-optimal solutions faster than uninformed search algorithms like BFS or DFS.
However, the performance of heuristic search algorithms heavily depends on the quality of the heuristic function. If the heuristic function is not admissible (overestimates the cost) or not consistent (does not satisfy the triangle inequality), the algorithm may not find the optimal solution or may expand more nodes than necessary.
Limitations and Tradeoffs
While binary search is a powerful algorithm, it‘s important to be aware of its limitations and tradeoffs when using it in AI and ML:
- Binary search requires the input data to be sorted, which can be a preprocessing overhead. If the data is frequently updated or not inherently sorted, maintaining the sorted order can be computationally expensive.
- Binary search is not suitable for searching in unordered or unstructured data, such as graphs or trees. In such cases, algorithms like BFS, DFS, or heuristic search may be more appropriate.
- Binary search assumes that the target value exists in the input data. If the target value is not present, binary search will return a negative result, indicating its absence. Additional logic may be needed to handle such cases.
- Binary search is a sequential algorithm and may not be easily parallelizable. If the input data is very large and parallelization is desired, other search algorithms or data structures (e.g., hash tables) may be more suitable.
When deciding whether to use binary search in an AI/ML context, it‘s crucial to consider these limitations and tradeoffs. The choice of search algorithm should be based on the specific requirements of the problem, the structure of the search space, and the desired performance characteristics.
Ongoing Research and Open Questions
Despite its simplicity and efficiency, binary search and its variants continue to be an active area of research in AI and ML. Here are a few ongoing research directions and open questions:
- Adaptive search algorithms: Researchers are exploring adaptive search algorithms that can dynamically adjust their search strategies based on the characteristics of the search space or the performance of the algorithm. These algorithms aim to combine the strengths of different search techniques and adapt to the problem at hand.
- Parallel and distributed search: With the increasing scale of AI and ML problems, there is a growing interest in parallel and distributed search algorithms that can leverage the power of multiple processors or machines. Developing efficient parallel and distributed versions of binary search and other search algorithms is an ongoing challenge.
- Search in high-dimensional spaces: Many AI and ML problems involve searching in high-dimensional spaces, such as feature spaces or parameter spaces. Binary search and other traditional search algorithms may not be directly applicable or efficient in such spaces. Researchers are investigating specialized search techniques and data structures for high-dimensional search, such as k-d trees, locality-sensitive hashing, and approximate nearest neighbor search.
- Integration with machine learning: There is a growing trend of integrating search algorithms with machine learning techniques to improve search performance and adaptability. For example, reinforcement learning can be used to learn search strategies or heuristics, while deep learning can be employed to learn compact representations of the search space.
These research directions highlight the ongoing efforts to push the boundaries of search algorithms and make them more efficient, scalable, and applicable to a wider range of AI and ML problems.
Conclusion
In this deep dive, we explored the binary search algorithm from an AI/ML perspective. We discussed its inner workings, analyzed its performance, and highlighted its potential applications in areas such as efficient searching in large datasets, feature selection, and hyperparameter tuning.
We also compared binary search with other search algorithms commonly used in AI, such as breadth-first search, depth-first search, and heuristic search, and discussed the limitations and tradeoffs of using binary search in different contexts.
Furthermore, we touched upon the ongoing research and open questions related to search algorithms in AI and ML, including adaptive search, parallel and distributed search, search in high-dimensional spaces, and integration with machine learning techniques.
As AI and ML continue to evolve and tackle increasingly complex problems, efficient search algorithms like binary search will remain valuable tools in the algorithmic toolbox. By understanding the strengths, limitations, and potential applications of binary search, AI/ML practitioners can make informed decisions and develop more efficient and effective solutions.
References
- Knuth, D. E. (1998). The Art of Computer Programming, Volume 3: Sorting and Searching. Addison-Wesley Professional.
- Russell, S. J., & Norvig, P. (2016). Artificial Intelligence: A Modern Approach. Pearson Education Limited.
- Goodfellow, I., Bengio, Y., & Courville, A. (2016). Deep Learning. MIT Press.
- Cormen, T. H., Leiserson, C. E., Rivest, R. L., & Stein, C. (2009). Introduction to Algorithms. MIT Press.
- Mehta, D. P., & Sahni, S. (2004). Handbook of Data Structures and Applications. Chapman and Hall/CRC.
Appendix: Binary Search Implementation
Here‘s a Python implementation of the binary search algorithm:
def binary_search(arr, target):
    low = 0
    high = len(arr) - 1

    while low <= high:
        mid = (low + high) // 2
        if arr[mid] == target:
            return mid
        elif arr[mid] < target:
            low = mid + 1
        else:
            high = mid - 1

    return -1
This implementation takes a sorted array arr and a target value target as input and returns the index of the target value if found, or -1 if not found.
The binary search algorithm maintains two pointers, low and high, which represent the range of indices where the target value can be found. Initially, low points to the first element, and high points to the last element of the array.
The algorithm then enters a loop that continues as long as low is less than or equal to high. In each iteration:
- The middle index
midis calculated as(low + high) // 2. - If the element at index
midis equal to the target value, the algorithm returnsmidas the index of the target value. - If the element at index
midis less than the target value, the algorithm updateslowtomid + 1to search in the right half of the array. - If the element at index
midis greater than the target value, the algorithm updateshightomid - 1to search in the left half of the array.
The loop continues until the target value is found or low becomes greater than high, indicating that the target value is not present in the array. In the latter case, the algorithm returns -1.
This implementation has a time complexity of O(log n), where n is the size of the input array, making it efficient for searching in large sorted arrays.
Feel free to use and modify this implementation based on your specific needs and programming language preferences.