A Beginner‘s Guide to Monte Carlo Simulation in R
Monte Carlo simulation is a powerful technique for modeling and analyzing systems with uncertainty. It allows you to quantify risk and make data-driven decisions by simulating many possible outcomes. While the concept may sound intimidating at first, performing Monte Carlo simulation is actually quite straightforward, especially using a statistical programming language like R.
In this article, we‘ll walk through the basics of Monte Carlo simulation and demonstrate how to implement it step-by-step in R. By the end, you‘ll be able to apply Monte Carlo methods to analyze uncertainty in your own projects. Let‘s get started!
What is Monte Carlo Simulation?
Monte Carlo simulation is a computational technique that uses repeated random sampling to model systems with uncertainty. The goal is to determine how variation impacts the sensitivity, performance or reliability of the system being modeled.
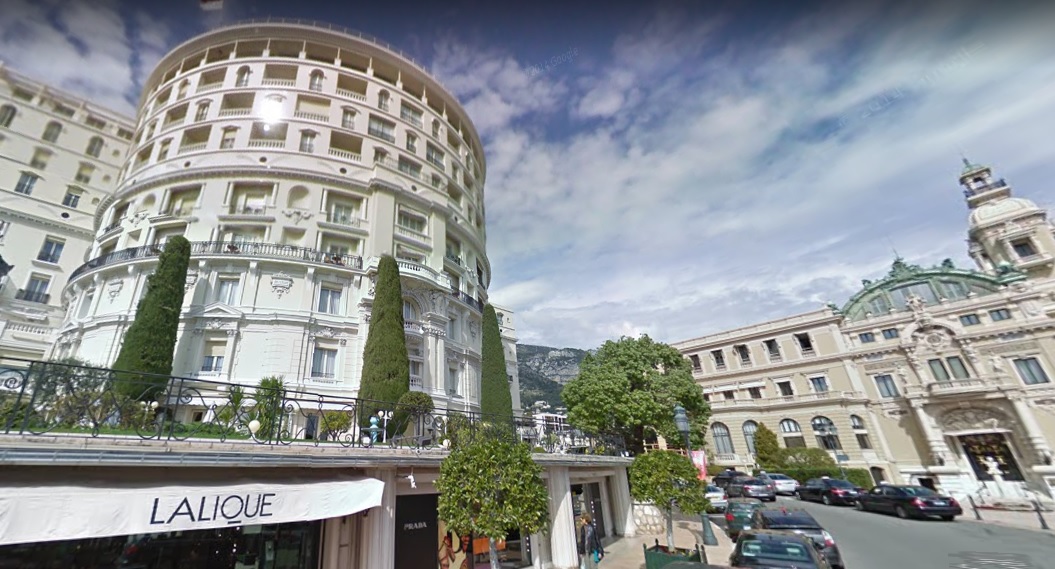
The term "Monte Carlo" was coined by physicist Nicholas Metropolis in the 1940s, in reference to the Monte Carlo Casino, where Metropolis‘ uncle often gambled. The link between a casino and this simulation technique is the use of randomness and repetitive sampling to find numerical results.
Some common applications of Monte Carlo simulation include:
- Estimating the probability of cost overruns or schedule delays in a project
- Predicting the range of potential future investment returns
- Modeling the spread of infectious diseases
- Analyzing tolerances in manufacturing and engineering
Why Use Monte Carlo Simulation?
One of the main advantages of Monte Carlo simulation is its ability to model uncertainty more realistically compared to alternative methods like probability distributions.
With Monte Carlo, the probability of different outcomes is found by actually running multiple trials with randomly selected variables, rather than assuming the variables follow convenient probability distributions like a normal distribution. This allows Monte Carlo methods to work with variables that have unusual or empirical distributions.
Monte Carlo simulation is especially useful when:
- The model is complex, nonlinear, or involves multiple uncertain parameters
- Parameters are correlated or have interdependencies
- You want to determine the full range of potential outcomes along with their probabilities
Compared to other techniques like propagation of error or sensitivity analysis, Monte Carlo simulation provides much richer information by generating a probability distribution of possible results rather than a single point estimate. It can uncover unexpected outcomes that other analyses might miss.
Steps to Perform Monte Carlo Simulation
While the specific implementation will depend on the system you are modeling, Monte Carlo simulation generally follows these key steps:
- Define the model and equations
- Identify input variables and their probability distributions
- Generate random samples from the probability distributions
- Run the simulation many times
- Analyze the results and quantify uncertainty
Let‘s examine each step in more detail, along with how to implement it in R.
Step 1: Define the Model
The first step is to define the mathematical model for the system you want to analyze. This involves specifying the equations and formulas that link the input variables to the output.
For example, let‘s say we want to estimate the probability that a construction project will exceed its budget. We have three cost categories (labor, materials, and overhead) and want to understand how variability in each category affects the total project cost.
Our model is fairly simple:
Total Cost = Labor + Materials + Overhead
Step 2: Identify Inputs & Distributions
Next, identify the key input variables that are uncertain and specify their possible values using probability distributions. These probability distributions capture your estimate of the inherent variability in each variable.
Some common probability distributions in Monte Carlo models include:
- Normal: bell-shaped, symmetrical distribution used for variables that could be higher or lower than the mean by a certain amount
- Uniform: all values have an equal probability, used when only the minimum and maximum are known
- Triangular: similar to normal but with specific minimum, maximum, and most likely values
- Discrete: used for variables that can only have integer values
For our construction project example, let‘s define the input variables and distributions:
- Labor cost follows a normal distribution with mean $100,000 and standard deviation $20,000
- Material cost follows a triangular distribution with minimum $50,000, most likely $60,000, and maximum $80,000
- Overhead cost follows a uniform distribution between $10,000 and $25,000
In R, we can define these distributions using the rnorm(), runif(), and rtriangle() functions:
labor <- rnorm(n=1000, mean=100000, sd=20000)
materials <- rtriangle(n=1000, a=50000, b=60000, c=80000)
overhead <- runif(n=1000, min=10000, max=25000)
Step 3: Generate Random Samples
With the probability distributions defined, the next step is to generate many random samples from each distribution. This process of generating random inputs that follow a certain probability distribution is the core of Monte Carlo simulation.
The number of samples generated for each variable will determine the number of times the simulation is run. A larger number of samples will produce more accurate results but take longer to run.
There is no set rule for how many iterations to run, but a good starting point is 1,000-10,000 samples, depending on the complexity of the model.
To generate 1,000 random samples for each input variable in R:
nsim <- 1000
labor_sim <- rnorm(n=nsim, mean=1e5, sd=2e4)
materials_sim <- rtriangle(n=nsim, a=5e4, b=6e4, c=8e4)
overhead_sim <- runif(n=nsim, min=1e4, max=2.5e4)
Step 4: Run the Simulation
Now that we have generated random inputs, we can run the simulation by evaluating the model with each set of sampled inputs.
In R, we can use vectorized operations to efficiently calculate the total cost for each of the 1,000 iterations:
total_cost_sim <- labor_sim + materials_sim + overhead_simThe result is a vector of 1,000 possible values for the total project cost, given the variability in the individual cost components.
Step 5: Analyze the Results
The final step is to analyze the results of the simulation and quantify the uncertainty. One of the key outputs is the probability distribution of the possible outcomes, which shows the relative likelihood of different results.
To visualize the distribution of simulated total costs in R:
hist(total_cost_sim, breaks=25, xlim=c(100000,300000),
     main="Distribution of Simulated Project Cost",
     xlab="Total Cost ($)")
By analyzing the distribution, we can calculate key statistics and probabilities, such as:
- The average or expected value
- Measures of spread like standard deviation or quantiles
- Probability of achieving a result above or below a threshold
For instance, to find the probability the project exceeds a budget of $250,000:
prob_over_budget <- mean(total_cost_sim > 250000)
print(paste0("Probability of exceeding budget = ",
             round(100*prob_over_budget, 2), "%"))
We can also use the percentiles of the simulated distribution to find a confidence interval for the total project cost:
cost_ci_90 <- quantile(total_cost_sim, c(0.05, 0.95))
print(paste0("90% confidence interval = $",
             round(cost_ci_90[1],-3), " to $",
             round(cost_ci_90[2],-3)))
Putting it all together, here is the complete code for running the Monte Carlo simulation of total project cost in R:
##Step 1: Define model
#Total Cost = Labor + Materials + Overhead

##Step 2: Define input variables and distributions
nsim <- 1000 #number of iterations to run

#Labor cost: normal dist with mean 100000 and stdev 20000
labor_sim <- rnorm(n=nsim, mean=1e5, sd=2e4)

#Materials cost: triangular dist with min 50000, ml 60000, max 80000
materials_sim <- rtriangle(n=nsim, a=5e4, b=6e4, c=8e4)

#Overhead cost: uniform dist between 10000 and 25000
overhead_sim <- runif(n=nsim, min=1e4, max=2.5e4)

##Step 3 & 4: Generate samples and run simulation
total_cost_sim <- labor_sim + materials_sim + overhead_sim

##Step 5: Analyze results
#Plot distribution of simulated costs
hist(total_cost_sim, breaks=25, xlim=c(100000,300000),
     main="Distribution of Simulated Project Cost",
     xlab="Total Cost ($)")

#Find probability of exceeding $250k budget
prob_over_budget <- mean(total_cost_sim > 250000)
print(paste0("Probability of exceeding budget = ",
             round(100*prob_over_budget, 2), "%"))

#Find 90% confidence interval for total cost
cost_ci_90 <- quantile(total_cost_sim, c(0.05, 0.95))
print(paste0("90% confidence interval = $",
             round(cost_ci_90[1],-3), " to $",
             round(cost_ci_90[2],-3)))
Best Practices for Monte Carlo Simulation
Here are some tips to keep in mind when performing Monte Carlo simulations:
-
Run an appropriate number of iterations: too few and the results won‘t be reliable, too many and it will take a long time to run with little extra benefit. Start with 1,000-10,000 and check the stability of the results.
-
Choose appropriate probability distributions for the input variables that match available data or domain knowledge. Many software packages include tools for fitting distributions to data.
-
Correlate input variables when necessary. Don‘t assume all inputs are independent if there are relationships between them.
-
Analyze the sensitivity of the results to the input distributions and model assumptions. Do the conclusions change significantly if you use a different distribution?
-
Validate and calibrate the model by comparing simulation outputs to historical or experimental data when possible. Refine the model if needed to match real-world results.
Limitations of Monte Carlo Simulation
While Monte Carlo simulation is a powerful tool for quantitative analysis, it‘s important to be aware of its limitations:
- The accuracy depends on the quality of the input data and validity of model assumptions. Garbage in still means garbage out.
- Rare events with extreme impacts may not be captured if you don‘t run enough iterations.
- Monte Carlo doesn‘t tell you why a system behaves a certain way, only what the range of outcomes is based on the specified model.
- Results can be misleading if the model is overly complex or input uncertainties are not characterized properly.
As with any model, it‘s critical to understand the assumptions and limitations, and interpret the results accordingly. Monte Carlo simulation is a valuable tool in the analyst‘s toolkit, but not a magic bullet.
Conclusion
Monte Carlo simulation is a flexible and powerful technique for incorporating uncertainty into quantitative analysis. By generating random inputs and running a model many times, it provides a fuller picture of the range of potential outcomes.
The key steps in performing Monte Carlo simulation are:
- Defining the model
- Specifying probability distributions for uncertain input variables
- Generating random samples from those distributions
- Running the simulation repeatedly
- Analyzing the distribution of results
With just a few lines of code, you can implement Monte Carlo simulation in R and apply it to a wide variety of real-world problems involving risk and uncertainty. The approach is not without limitations, but with proper understanding and application, Monte Carlo simulation is an indispensable tool for data-driven decision making.