A Deep Dive into Neural Radiance Fields (NeRF): Revolutionizing 3D Scene Representation
Introduction
Neural Radiance Fields (NeRF) have emerged as a groundbreaking technique in the field of computer vision and graphics, enabling the creation of photorealistic 3D scenes from a collection of 2D images. By leveraging the power of deep learning, NeRF can learn a compact and continuous representation of a scene, allowing for high-quality novel view synthesis and immersive 3D experiences. In this article, we will delve into the technical details of NeRF, explore its architecture, training process, and applications, and discuss its significance in the broader context of artificial intelligence and machine learning.
Understanding Neural Radiance Fields
At its core, a Neural Radiance Field is a continuous function that maps a 5D input coordinate (3D spatial location and 2D viewing direction) to an emitted color and volume density at that point in space. Mathematically, it can be expressed as:
(r, g, b, σ) = F(x, y, z, θ, ϕ)
where (x, y, z) represents the 3D spatial coordinate, (θ, ϕ) represents the 2D viewing direction, and (r, g, b, σ) represents the output color and volume density.
The key idea behind NeRF is to represent a 3D scene as a neural network that can be queried at any continuous 5D coordinate to obtain the corresponding appearance and geometry information. By training this neural network on a dataset of posed images, NeRF can learn to interpolate between the observed views and generate novel views of the scene with remarkable realism and consistency.
NeRF Architecture
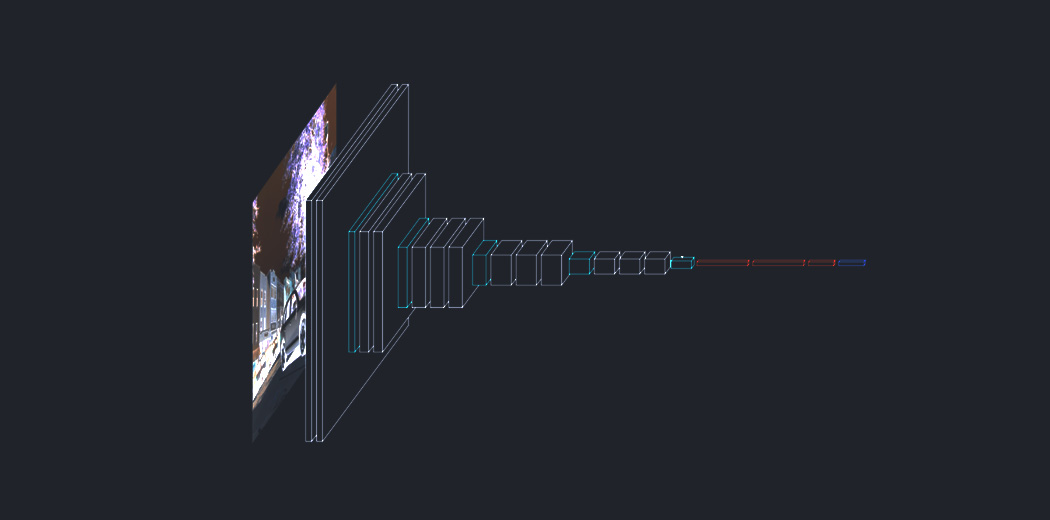
The NeRF model architecture consists of a fully-connected neural network, also known as a multi-layer perceptron (MLP). The input to the network is a 5D coordinate (x, y, z, θ, ϕ), which undergoes a series of positional encoding transformations to map it into a higher-dimensional space. This encoding helps the network learn high-frequency details and improves the reconstruction quality.
The encoded input is then passed through a sequence of fully-connected layers, typically ranging from 8 to 12 layers, with ReLU activation functions. The hidden layers gradually transform the input into a 4D output vector representing the RGB color (r, g, b) and volume density (σ) at the corresponding 3D point.
One crucial aspect of the NeRF architecture is the use of a hierarchical sampling scheme during rendering. Instead of densely evaluating the MLP at every point along a camera ray, NeRF employs a coarse-to-fine approach. It first evaluates the scene at a sparse set of sample points and then uses the predicted densities to guide a second round of finer sampling. This hierarchical sampling allows the network to efficiently allocate computational resources to regions of importance and reduces the overall rendering time.
Training NeRF Models
Training a NeRF model involves optimizing the parameters of the MLP to minimize the difference between the rendered views and the ground-truth images. The training process typically consists of the following steps:
-
Data Preparation: A dataset of posed images of the target scene is collected, along with their corresponding camera parameters (position, orientation, and field of view). Rays are cast from each pixel of each image into the 3D scene, and the corresponding 3D points and viewing directions are sampled along each ray.
-
Forward Pass: The sampled 5D coordinates are passed through the NeRF MLP to predict the colors and densities at each point. The predicted values are then composited using volume rendering techniques to obtain the rendered pixel colors.
-
Loss Computation: The rendered pixel colors are compared with the ground-truth pixel colors from the input images using a loss function. Common loss functions used for NeRF training include mean squared error (MSE) and peak signal-to-noise ratio (PSNR). The goal is to minimize the difference between the rendered and ground-truth images.
-
Optimization: The gradients of the loss with respect to the NeRF model parameters are computed using backpropagation. These gradients are then used to update the model weights using an optimization algorithm such as stochastic gradient descent (SGD) or Adam.
The training process is repeated for a specified number of iterations or until convergence. The choice of hyperparameters, such as learning rate, batch size, and the number of sampling points, can significantly impact the training time and the quality of the reconstructed scene.
Challenges and Trade-offs
While NeRF has demonstrated impressive results in novel view synthesis, it also comes with certain challenges and trade-offs. One major challenge is the computational cost associated with rendering high-resolution images. As each pixel requires multiple evaluations of the MLP along the camera ray, the rendering process can be time-consuming, especially for complex scenes.
Another challenge is handling complex geometries and view-dependent effects. NeRF relies on the ability of the MLP to learn and represent intricate scene details, which can be challenging for scenes with thin structures, transparency, or specular reflections. Capturing these effects accurately may require more sophisticated network architectures or additional input information.
Moreover, the training process of NeRF can be resource-intensive and time-consuming, particularly for large-scale scenes or high-resolution images. Balancing the reconstruction quality and training time is a key consideration when deploying NeRF in practical applications.
Applications and Impact
Neural Radiance Fields have opened up exciting possibilities in various domains, revolutionizing the way we capture, represent, and interact with 3D scenes. Some notable applications of NeRF include:
-
3D Object Digitization: NeRF can be used to digitize real-world objects by capturing a set of images from different viewpoints and reconstructing a photorealistic 3D model. This has applications in e-commerce, product visualization, and cultural heritage preservation.
-
Virtual Tours and Immersive Experiences: By learning a continuous representation of a scene, NeRF enables the creation of interactive virtual tours and immersive experiences. Users can explore a captured environment from any viewpoint, providing a realistic and engaging experience.
-
Visual Effects and Content Creation: NeRF can be utilized in the film and gaming industry for creating photorealistic visual effects and virtual environments. It allows for the seamless integration of computer-generated content with real-world footage, enhancing the realism and immersion of the final output.
-
Autonomous Navigation: In the field of robotics and autonomous systems, NeRF can serve as a compact and efficient representation of 3D environments. By learning a continuous scene representation, robots can navigate and interact with their surroundings more effectively, enabling advanced perception and planning capabilities.
The impact of NeRF extends beyond specific applications and has broader implications for the field of AI and machine learning. NeRF demonstrates the power of deep learning in capturing and representing complex 3D scenes, opening up new avenues for research in computer vision, graphics, and generative models.
Furthermore, NeRF has connections to other areas of AI, such as self-supervised learning and unsupervised representation learning. The ability to learn a compact and meaningful representation of a scene from raw images aligns with the goal of self-supervised learning, where the model learns to extract useful features and representations without explicit annotations.
Conclusion
Neural Radiance Fields have emerged as a transformative technique in the field of computer vision and graphics, enabling the creation of photorealistic 3D scenes from a set of 2D images. By representing a scene as a continuous function parameterized by a neural network, NeRF can render high-quality novel views with remarkable consistency and realism.
The NeRF architecture, based on a fully-connected MLP with positional encoding and hierarchical sampling, has shown impressive results in capturing complex geometries and view-dependent effects. However, challenges such as computational cost, training time, and handling intricate scene details remain areas of active research and development.
The applications of NeRF span across various domains, including 3D object digitization, virtual tours, visual effects, and autonomous navigation. The impact of NeRF extends beyond specific use cases and has broader implications for the field of AI and machine learning, demonstrating the power of deep learning in capturing and representing complex 3D scenes.
As research in Neural Radiance Fields continues to advance, we can anticipate further improvements in rendering quality, efficiency, and generalization capabilities. The integration of NeRF with other AI techniques, such as self-supervised learning and generative models, holds promise for even more sophisticated and versatile scene representation and rendering approaches.
In conclusion, Neural Radiance Fields have revolutionized the way we capture, represent, and interact with 3D scenes, opening up exciting possibilities for photorealistic rendering, immersive experiences, and advanced perception and navigation capabilities. As an AI and machine learning expert, I believe that NeRF will continue to play a significant role in shaping the future of computer vision, graphics, and beyond, driving innovation and pushing the boundaries of what is possible in the realm of 3D scene understanding and synthesis.