Sentiment Analysis with NLP & Deep Learning: A Comprehensive Guide
Introduction
In today‘s data-driven world, understanding and analyzing public opinion and sentiment has become crucial for businesses, organizations, and individuals alike. Sentiment analysis, a subfield of natural language processing (NLP), plays a vital role in extracting insights from vast amounts of textual data. By leveraging the power of NLP and deep learning techniques, sentiment analysis enables us to automatically determine the emotional tone and opinion expressed in text data, such as customer reviews, social media posts, and survey responses.
In this comprehensive guide, we will delve into the fascinating world of sentiment analysis, exploring its concepts, techniques, and applications. We will discover how NLP and deep learning have revolutionized sentiment analysis, enabling more accurate and efficient analysis of textual data. By the end of this article, you will have a solid understanding of sentiment analysis and be equipped with the knowledge to implement sentiment analysis models using state-of-the-art deep learning architectures.
Understanding Sentiment Analysis
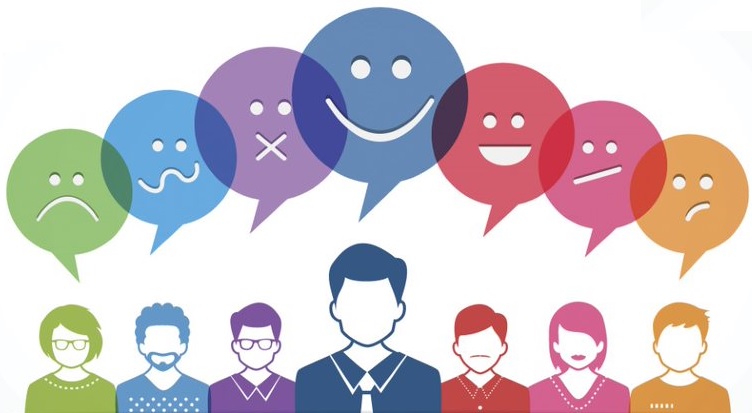
At its core, sentiment analysis aims to determine the sentiment or emotion expressed in a piece of text. It involves classifying text into predefined sentiment categories, such as positive, negative, or neutral. Sentiment analysis goes beyond simple keyword matching and takes into account the context, semantics, and linguistic nuances present in the text.
The applications of sentiment analysis are vast and diverse. Businesses utilize sentiment analysis to gauge customer satisfaction, monitor brand reputation, and identify areas for improvement. It helps companies to proactively address customer concerns and make data-driven decisions. In the realm of social media, sentiment analysis enables organizations to track public opinion, detect emerging trends, and respond to crises in real-time.
However, sentiment analysis is not without its challenges. Sarcasm, irony, and negation are often difficult to detect and can lead to misinterpretation of sentiment. Additionally, sentiment can vary across different domains, cultures, and languages, making it crucial to adapt sentiment analysis models to specific contexts.
Natural Language Processing (NLP) for Sentiment Analysis
Natural Language Processing (NLP) forms the foundation of sentiment analysis. NLP techniques enable computers to understand, interpret, and manipulate human language. In the context of sentiment analysis, NLP plays a crucial role in preprocessing and transforming raw text data into a format suitable for analysis.
Text preprocessing is a vital step in sentiment analysis. It involves tasks such as tokenization (splitting text into individual words or tokens), lowercasing (converting all text to lowercase), stop word removal (eliminating common words like "a," "an," "the"), and stemming or lemmatization (reducing words to their base or dictionary form). These preprocessing techniques help to normalize the text and reduce noise, enabling more accurate sentiment analysis.
Feature extraction is another essential aspect of NLP in sentiment analysis. It involves converting the preprocessed text into numerical representations that machine learning algorithms can understand. Common feature extraction methods include Bag-of-Words (BoW), which represents text as a vector of word frequencies, and Term Frequency-Inverse Document Frequency (TF-IDF), which assigns weights to words based on their importance in the text corpus. More advanced techniques, such as word embeddings (e.g., Word2Vec, GloVe), capture semantic relationships between words and provide dense vector representations.
Sentiment lexicons are also valuable resources in sentiment analysis. These lexicons contain lists of words and their associated sentiment scores, allowing for quick and simple sentiment classification based on the presence of sentiment-bearing words. However, lexicon-based approaches have limitations, as they may not capture the full context and nuances of the text.
Deep Learning Architectures for Sentiment Analysis
Deep learning has revolutionized sentiment analysis by enabling more sophisticated and accurate models. Deep learning architectures, such as Recurrent Neural Networks (RNNs) and Convolutional Neural Networks (CNNs), have shown remarkable performance in capturing the complex patterns and dependencies present in text data.
RNNs, particularly Long Short-Term Memory (LSTM) and Gated Recurrent Units (GRU), are well-suited for processing sequential data like text. They can capture long-term dependencies and maintain contextual information, making them effective for sentiment analysis tasks. LSTMs and GRUs address the vanishing gradient problem encountered in traditional RNNs, allowing for better preservation of long-range dependencies.
CNNs, originally designed for image classification, have also been successfully applied to text classification tasks, including sentiment analysis. CNNs can capture local patterns and extract relevant features from text data. They are particularly effective in handling short and medium-length text, such as tweets or product reviews.
Attention mechanisms have further enhanced the performance of deep learning models for sentiment analysis. Attention allows the model to focus on the most relevant parts of the text when making predictions, improving the model‘s interpretability and accuracy. Transformers, a type of attention-based architecture, have achieved state-of-the-art results in various NLP tasks, including sentiment analysis.
Transfer learning and pre-trained language models, such as BERT (Bidirectional Encoder Representations from Transformers) and GPT (Generative Pre-trained Transformer), have also significantly impacted sentiment analysis. These models are pre-trained on massive amounts of unlabeled text data and can be fine-tuned for specific sentiment analysis tasks. They capture rich semantic information and have shown impressive results in sentiment classification.
Building a Sentiment Analysis Model
Building a sentiment analysis model involves several key steps, including dataset preparation, model selection, training, and evaluation.
Dataset preparation is crucial for sentiment analysis. It involves collecting relevant text data, such as customer reviews or social media posts, and preprocessing it using NLP techniques discussed earlier. Labeling the data with sentiment labels (e.g., positive, negative, neutral) is also necessary for supervised learning approaches.
Choosing the appropriate deep learning architecture depends on the nature of the text data and the specific requirements of the sentiment analysis task. RNNs (LSTM, GRU) are suitable for longer text sequences, while CNNs are effective for shorter text. Attention mechanisms and pre-trained language models can further enhance the model‘s performance.
Model training involves feeding the preprocessed and labeled data into the chosen deep learning architecture. The model learns to map the input text to the corresponding sentiment labels by adjusting its internal parameters through optimization techniques like gradient descent. Hyperparameter tuning, such as selecting the appropriate learning rate, batch size, and number of epochs, is essential to achieve optimal performance.
Evaluation metrics are used to assess the performance of the trained sentiment analysis model. Common metrics include accuracy, precision, recall, and F1-score. Accuracy measures the overall correctness of the model‘s predictions, while precision and recall focus on the model‘s ability to identify positive and negative sentiments accurately. The F1-score provides a balanced measure by combining precision and recall.
Handling imbalanced datasets is a common challenge in sentiment analysis. Imbalanced datasets occur when the distribution of sentiment labels is skewed, with one class (e.g., positive) having significantly more instances than the other (e.g., negative). Techniques such as oversampling the minority class, undersampling the majority class, or using class weights can help mitigate the impact of imbalanced datasets.
Case Study: Sentiment Analysis of Product Reviews
To illustrate the practical application of sentiment analysis, let‘s consider a case study involving the analysis of product reviews.
The problem statement is to develop a sentiment analysis model that can automatically classify product reviews as positive, negative, or neutral. The goal is to provide valuable insights to businesses about customer satisfaction and identify areas for product improvement.
The first step is data collection and preprocessing. Product reviews can be collected from various sources, such as e-commerce websites or review platforms. The collected reviews are then preprocessed using NLP techniques, including tokenization, lowercasing, stop word removal, and stemming or lemmatization.
Exploratory Data Analysis (EDA) is performed to gain initial insights into the dataset. This involves analyzing the distribution of sentiment labels, identifying common words or phrases associated with each sentiment, and visualizing the data using word clouds or frequency plots.
Next, the sentiment analysis model is built and trained using a suitable deep learning architecture, such as LSTM or CNN. The preprocessed reviews are split into training and validation sets, and the model is trained on the training set using appropriate hyperparameters.
After training, the model‘s performance is evaluated using metrics like accuracy, precision, recall, and F1-score on the validation set. The model‘s predictions are compared against the actual sentiment labels to assess its effectiveness in classifying product reviews accurately.
Finally, the trained model is used to generate insights and actionable recommendations. The model can identify the overall sentiment towards the product, highlight specific aspects or features that customers appreciate or criticize, and provide valuable feedback for product improvement. These insights can help businesses make data-driven decisions and enhance customer satisfaction.
Challenges and Future Directions
Sentiment analysis, while powerful, still faces several challenges that require ongoing research and development.
One significant challenge is handling sarcasm, irony, and negation in text data. Sarcasm and irony involve expressing sentiments that are opposite to the literal meaning of the words used. Negation, such as "not good," can also invert the sentiment of a phrase. Detecting and accurately interpreting these linguistic phenomena is an active area of research in sentiment analysis.
Multilingual sentiment analysis is another challenge, as sentiment can vary across different languages and cultural contexts. Developing sentiment analysis models that can handle multiple languages and account for cultural nuances is crucial for global applications.
Aspect-based sentiment analysis is an emerging trend that aims to identify sentiment towards specific aspects or features of a product or service. Instead of providing an overall sentiment score, aspect-based sentiment analysis provides fine-grained insights into customer opinions on different aspects, such as product quality, price, or customer service.
Real-time sentiment analysis of streaming data, such as social media feeds or customer support conversations, presents its own set of challenges. Handling the volume, velocity, and variety of streaming data requires efficient and scalable sentiment analysis models that can process and analyze data in near real-time.
Ethical considerations in sentiment analysis are also gaining attention. Ensuring privacy, fairness, and transparency in sentiment analysis models is crucial to prevent biased or discriminatory outcomes. Researchers and practitioners must adhere to ethical guidelines and consider the potential societal impact of sentiment analysis applications.
Conclusion
Sentiment analysis has emerged as a powerful tool for extracting insights and understanding public opinion from vast amounts of textual data. By leveraging the advancements in natural language processing (NLP) and deep learning, sentiment analysis models can accurately classify text into sentiment categories, enabling businesses and organizations to make data-driven decisions and improve customer satisfaction.
Throughout this article, we explored the concepts and techniques involved in sentiment analysis, from text preprocessing and feature extraction to deep learning architectures like RNNs and CNNs. We discussed the challenges faced in sentiment analysis, such as handling sarcasm, irony, and negation, and highlighted future directions, including multilingual sentiment analysis, aspect-based sentiment analysis, and real-time sentiment analysis of streaming data.
The case study on sentiment analysis of product reviews demonstrated the practical application of sentiment analysis in a business context. By analyzing customer feedback, businesses can gain valuable insights into product strengths, weaknesses, and areas for improvement, ultimately leading to enhanced customer satisfaction and competitive advantage.
As sentiment analysis continues to evolve, it is essential for researchers and practitioners to stay updated with the latest advancements and best practices. Ethical considerations should also be at the forefront of sentiment analysis applications to ensure fairness, transparency, and privacy.
We encourage readers to explore sentiment analysis further, experiment with different deep learning architectures, and apply sentiment analysis techniques to real-world problems. By harnessing the power of NLP and deep learning, sentiment analysis has the potential to unlock valuable insights and drive positive change in various domains, from business and marketing to social sciences and beyond.