Decision Trees Demystified: A Step-by-Step Guide to How They Work
Decision trees are one of the most popular and intuitive machine learning algorithms, used for both classification and regression tasks. Their popularity stems from the fact that they are easy to understand and interpret, handle both categorical and numerical data, require little data preparation, and can model non-linear relationships.
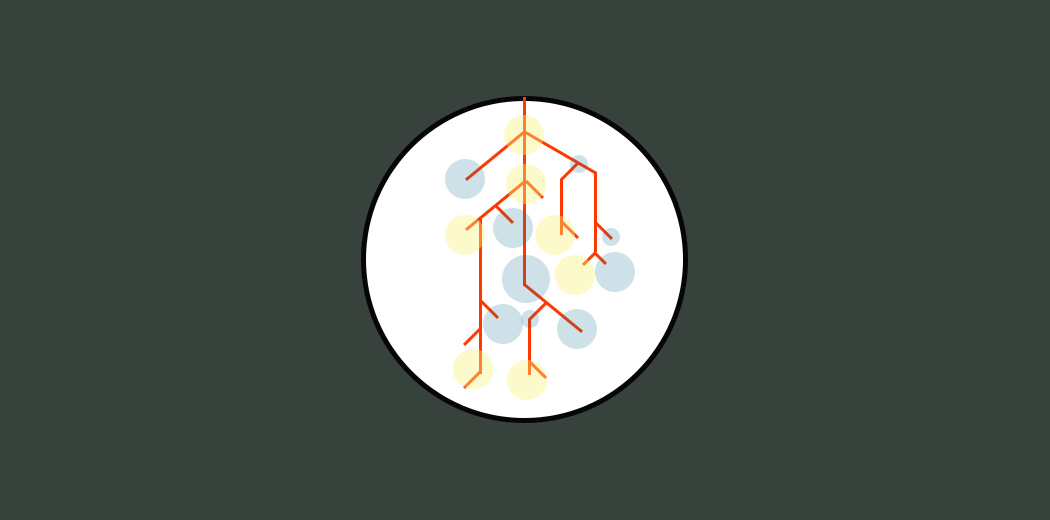
At a high level, a decision tree makes predictions by learning a hierarchy of if-then-else decision rules from training data. It recursively splits the data into subsets based on the most informative feature at each node. The resulting model is a binary tree, where each internal node represents a decision based on a single feature, and each leaf node contains a prediction.
Let‘s dive into the step-by-step process of how decision trees are built, using the well-known ID3 algorithm as an example.
Step 1: Choosing the Best Split
The crux of the decision tree algorithm is selecting which attribute to split on at each node that will best separate the examples. We want splits that result in the "purest" subsets, where the target variable has the least mixing of classes.
Several mathematical criteria can measure node impurity, but the two most common are:
Gini Impurity
Gini impurity is the probability of misclassifying a randomly chosen element if it were labeled randomly according to the class distribution. It reaches zero when a node contains only examples from a single class.
The Gini impurity of a set of items with J classes is calculated as:
Gini = 1 – Σ(pj)^2
where pj is the fraction of items labeled with class j
Entropy and Information Gain
Entropy is a measure of the "surprisal" or uncertainty in a random variable. The more skewed the class distribution, the lower the entropy. It is calculated as:
Entropy = -Σ(pj * log2(pj))
Information gain is the difference in entropy before and after the split. Attributes with the highest information gain are preferred.
Gain(T,X) = Entropy(T) – Σ( |Tx| / |T| * Entropy(Tx) )
where T is the current set and Tx are the subsets created by splitting on attribute X.
Comparing Gini vs Entropy
Both Gini impurity and entropy lead to similar trees, but Gini is slightly faster to compute. Gini tends to isolate the most frequent class in its own branch, while entropy tends to produce slightly more balanced trees.
Step 2: Recursively Split Nodes
The decision tree is constructed top-down in a greedy fashion, starting with the entire training set at the root node.
At each node:
- If all examples belong to the same class, return a leaf node with that class label
- Otherwise, evaluate each attribute using the chosen impurity metric and select the one with the best score
- Create a decision node based on the selected attribute
- Recurse on the child nodes using their respective subsets of the data
This process continues until a stopping criteria is hit, such as:
- All examples in a node have the same target value
- The maximum tree depth is reached
- The number of examples in a node is below some threshold
- The gain from additional splits is below some threshold
Handling Different Attribute Types
Categorical Attributes
For a categorical attribute with V possible values, the data is partitioned into V subsets, one for each value. The impurity of each subset is calculated, and the attribute‘s final impurity is the weighted average of subset impurities.
Continuous Attributes
For continuous attributes, the data is first sorted by the attribute value. Potential split points are identified between each pair of adjacent values. The point that results in the highest gain when splitting the data is selected.
Note that continuous attributes are always partitioned into 2 subsets in a binary decision tree, corresponding to X < t and X >= t for the chosen threshold t.
Pruning the Tree
Decision trees tend to overfit training data if grown to full depth. To limit this, the tree can be "pruned" after construction by removing branches that do not add sufficient predictive power. Two common approaches are:
Pre-pruning
Halts the tree construction early by setting a threshold for the minimum gain required to make additional splits. Higher thresholds result in smaller trees.
Post-pruning
Allows the tree to fully grow, then recursively prunes nodes whose removal does not significantly reduce accuracy on a validation set. Pruning continues until further removal starts increasing the validation error.
Making Predictions
To classify a new example using the learned tree:
- Start at the root node
- Evaluate the example‘s relevant attribute at each node and follow the corresponding branch based on the attribute‘s value
- Continue until a leaf node is reached
- Return the class label associated with the final leaf node as the prediction
- For regression trees, return the average target value of training examples in the leaf
Advantages of Decision Trees
- Simple to understand and interpret
- Able to handle both numerical and categorical data
- Require little data preparation (no need for normalization or scaling)
- Perform well on large datasets
- Robust to outliers and missing values
- Model non-linear relationships and feature interactions
- Outputs are easy to visualize and explain (white-box model)
- Can be used for feature selection / importance ranking
Disadvantages of Decision Trees
- Prone to overfitting, especially if the tree is deep
- Small variations in the data can result in very different trees (high variance)
- Greedy algorithms cannot guarantee to return the globally optimal tree
- Biased trees can be created if some classes dominate
- Struggles with very unbalanced datasets
- Unstable when dealing with many features of similar relevance
- Cannot natively handle very sparse data (many irrelevant features)
- Calculations can get complex for data with many class labels
Applications of Decision Trees
Decision trees are used in many real-world domains such as:
- Medical diagnosis based on symptoms
- Loan approval based on applicant profile
- Equipment malfunction detection based on sensor readings
- Customer churn prediction based on account activity
- Classifying galaxies based on telescope data
- Predicting student performance based on study habits
Decision trees are also commonly used as base learners in ensemble methods like random forests and gradient boosting machines, which combine many trees to make more robust predictions.
Implementing Decision Trees in Python
Luckily, we don‘t have to code decision trees from scratch, as optimized implementations are available in popular machine learning libraries. The two most common are:
Scikit-Learn
from sklearn.tree import DecisionTreeClassifier
model = DecisionTreeClassifier(criterion=‘gini‘, max_depth=5)
model.fit(X_train, y_train)
predictions = model.predict(X_test)
XGBoost
import xgboost as xgb
model = xgb.XGBClassifier(max_depth=5, learning_rate=0.1)
model.fit(X_train, y_train)
predictions = model.predict(X_test)
Hyperparameter Tuning
The performance of decision trees is sensitive to several key hyperparameters:
- Maximum tree depth
- Minimum number of samples to split an internal node
- Minimum number of samples required at a leaf node
- Maximum number of features to consider at each split
To find the optimal settings, we can use grid search or random search with cross-validation. Libraries like scikit-learn make this easy:
from sklearn.model_selection import GridSearchCV
parameters = {‘max_depth‘:[3,5,10], ‘min_samples_split‘:[2,5,10]}
model = DecisionTreeClassifier()
cv = GridSearchCV(model, parameters, cv=5)
cv.fit(X_train, y_train)
print(cv.bestparams)
Conclusion
We‘ve covered the key steps of how decision trees are built, including selecting the best splits, recursively partitioning nodes, handling different attribute types, pruning to avoid overfitting, and making predictions on new examples.
While decision trees come with several pitfalls, such as a tendency to overfit and instability with small data variations, they remain one of the most popular algorithms in the data scientist‘s toolkit due to their simplicity, interpretability, and robustness to messy data.
Their ability to model non-linear relationships, handle numerical and categorical features, and provide direct feature importance scores make them an indispensable tool for both predictive modeling and data exploration tasks across a wide variety of domains.
I hope this in-depth guide helped clarify how decision trees work under the hood! Let me know in the comments if you have any other questions.