A Detailed Guide to Univariate Anomaly Detection in Python
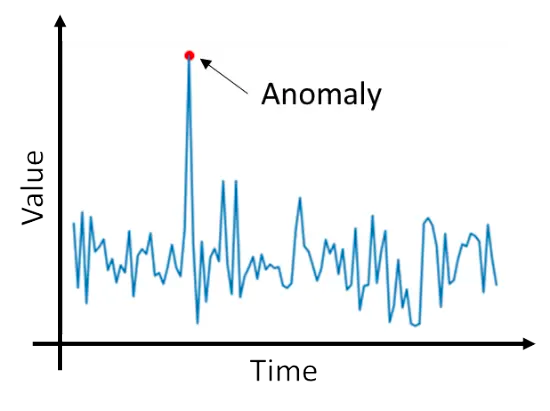
Anomaly detection is a common and important task in data analysis. The goal is to identify rare items or events in data that differ significantly from the majority. These anomalous data points, often called outliers, can represent bank fraud, defective equipment, medical problems, or other issues that are important to detect.
While anomaly detection can be applied to datasets with many features (multivariate anomaly detection), in this guide we‘ll focus on the case of univariate anomaly detection – finding anomalies in a single variable. We‘ll walk through an end-to-end example in Python, focusing especially on the isolation forest algorithm.
What is Univariate Anomaly Detection?
In univariate anomaly detection, we have a single variable or feature and want to identify values that are unusually high or low compared to the rest of the data. Some common examples:
- Finding spikes or dips in time-series data, like a sudden drop in a sensor reading
- Identifying transactions with unusually large amounts in banking data
- Detecting equipment that is reporting abnormal measurement values
The key characteristic is that we‘re only considering a single variable in isolation, rather than multiple variables together. This is useful when we expect anomalies to show up clearly in an individual feature. It also lets us visualize the data and anomalies easily with simple plots.
An End-to-End Example
Let‘s demonstrate the process with an example. We‘ll use a dataset of reported product sales amounts over a 30-day period:
import pandas as pd
import matplotlib.pyplot as plt

data = pd.DataFrame([
    [‘2024-06-01‘, 53001.45],
    [‘2024-06-02‘, 49872.36],
    [‘2024-06-03‘, 1242389.23],
    [‘2024-06-04‘, 55492.16],
    ...
], columns=[‘date‘, ‘amount‘])
Here the amount column is the variable we want to analyze. We can start by plotting a histogram to visualize the distribution:
plt.hist(data[‘amount‘], bins=30)
plt.xlabel(‘Sales Amount ($)‘)
plt.ylabel(‘Frequency‘)
plt.show()
From the histogram, we can see that most days have sales in the range of $50,000-$75,000, but there are a few unusually high amounts above $1,000,000 that could be anomalies. Let‘s use the isolation forest algorithm to detect them.
Isolation Forest for Anomaly Detection
The isolation forest algorithm is a powerful and flexible approach that is very effective for finding anomalies, especially in high-dimensional data.
Here‘s a quick overview of how it works:
-
Isolation forest builds an ensemble of decision trees (called isolation trees).
-
Each isolation tree recursively partitions the data by randomly selecting a feature and split value until every data point is isolated in its own leaf node.
-
Since anomalies are rare and different from normal points, they require fewer splits to be isolated in a leaf node. So anomalies tend to have shorter paths in the isolation trees.
-
To get an anomaly score for a data point, isolation forest averages the path length across all trees. Points with short average path lengths are considered more likely to be anomalies.
One big advantage of isolation forest is that it doesn‘t rely on distance or density measures, which can break down in high dimensions. It‘s also fast, scalable, and handles irrelevant features well.
Here‘s how we can apply isolation forest to our sales data:
from sklearn.ensemble import IsolationForest

model = IsolationForest(n_estimators=100, contamination=0.01)
model.fit(data[[‘amount‘]])

data[‘anomaly‘] = model.predict(data[[‘amount‘]])
This trains an isolation forest model with 100 trees and an expected anomaly fraction of 1%. After fitting the model, we apply it to the data to get anomaly labels of 1 (normal) or -1 (anomaly).
Plotting the results:
anomalies = data.loc[data[‘anomaly‘] == -1]

plt.figure(figsize=(10,4))
plt.plot(data[‘date‘], data[‘amount‘], color=‘blue‘, label=‘Normal‘)
plt.scatter(anomalies[‘date‘], anomalies[‘amount‘], color=‘red‘, label=‘Anomaly‘)
plt.xticks(rotation=90)
plt.legend()
plt.show()
The plot shows that isolation forest has identified the few very large values as anomalies, which matches our intuition from the histogram. We could follow up on these cases to determine if they represent data errors, fraudulent transactions, or real but highly unusual sales.
Evaluating and Tuning Anomaly Detection Models
Evaluating an anomaly detection model is tricky since there‘s often no ground truth labels. A few strategies:
- Manual review: Have a domain expert review the top anomalies detected to judge if they‘re unusual and actionable
- Synthetic anomalies: Inject labeled anomalies into a normal dataset and measure the model‘s precision/recall
- Supervised approach: If some true anomalies are labeled, measure detection accuracy on them
Some key parameters to tune for isolation forest:
n_estimators: More trees improves performance but costs memory and runtime. Typical values are 100-1000.contamination: The expected fraction of anomalies. Setting this correctly can improve results, but the algorithm is fairly robust to this parameter.max_samples: Sampling size for building trees. Lower values provide faster training but may impact accuracy.
Other Anomaly Detection Algorithms
Some other popular algorithms for univariate anomaly detection include:
- Z-score: Detects values that are a certain number of standard deviations from the mean
- Interquartile range (IQR): Identifies values below Q1 – 1.5IQR or above Q3 + 1.5IQR as outliers
- DBSCAN: Clustering-based method that labels points with few nearby neighbors as anomalies
- One-class SVM: Learns a decision boundary around normal points and treats points outside as anomalies
The PyOD library provides a great interface for experimenting with different anomaly detection algorithms.
Conclusion and Next Steps
In this guide, we covered the basics of univariate anomaly detection and walked through an example using the isolation forest algorithm in Python. We saw how isolation forest effectively finds unusual values and how to visualize and interpret the results.
Next steps to dive deeper into anomaly detection:
- Experiment with other algorithms like one-class SVM or local outlier factor
- Explore multivariate anomaly detection on datasets with many features
- Learn about other applications like anomaly detection on time-series, text, or graph data
The complete code for this example is available on Github. Try running it yourself and extend it to your own datasets! With practice, anomaly detection can be a powerful tool to discover valuable insights from your data.