Mastering the Data Science Project Lifecycle: An AI/ML Expert‘s Guide
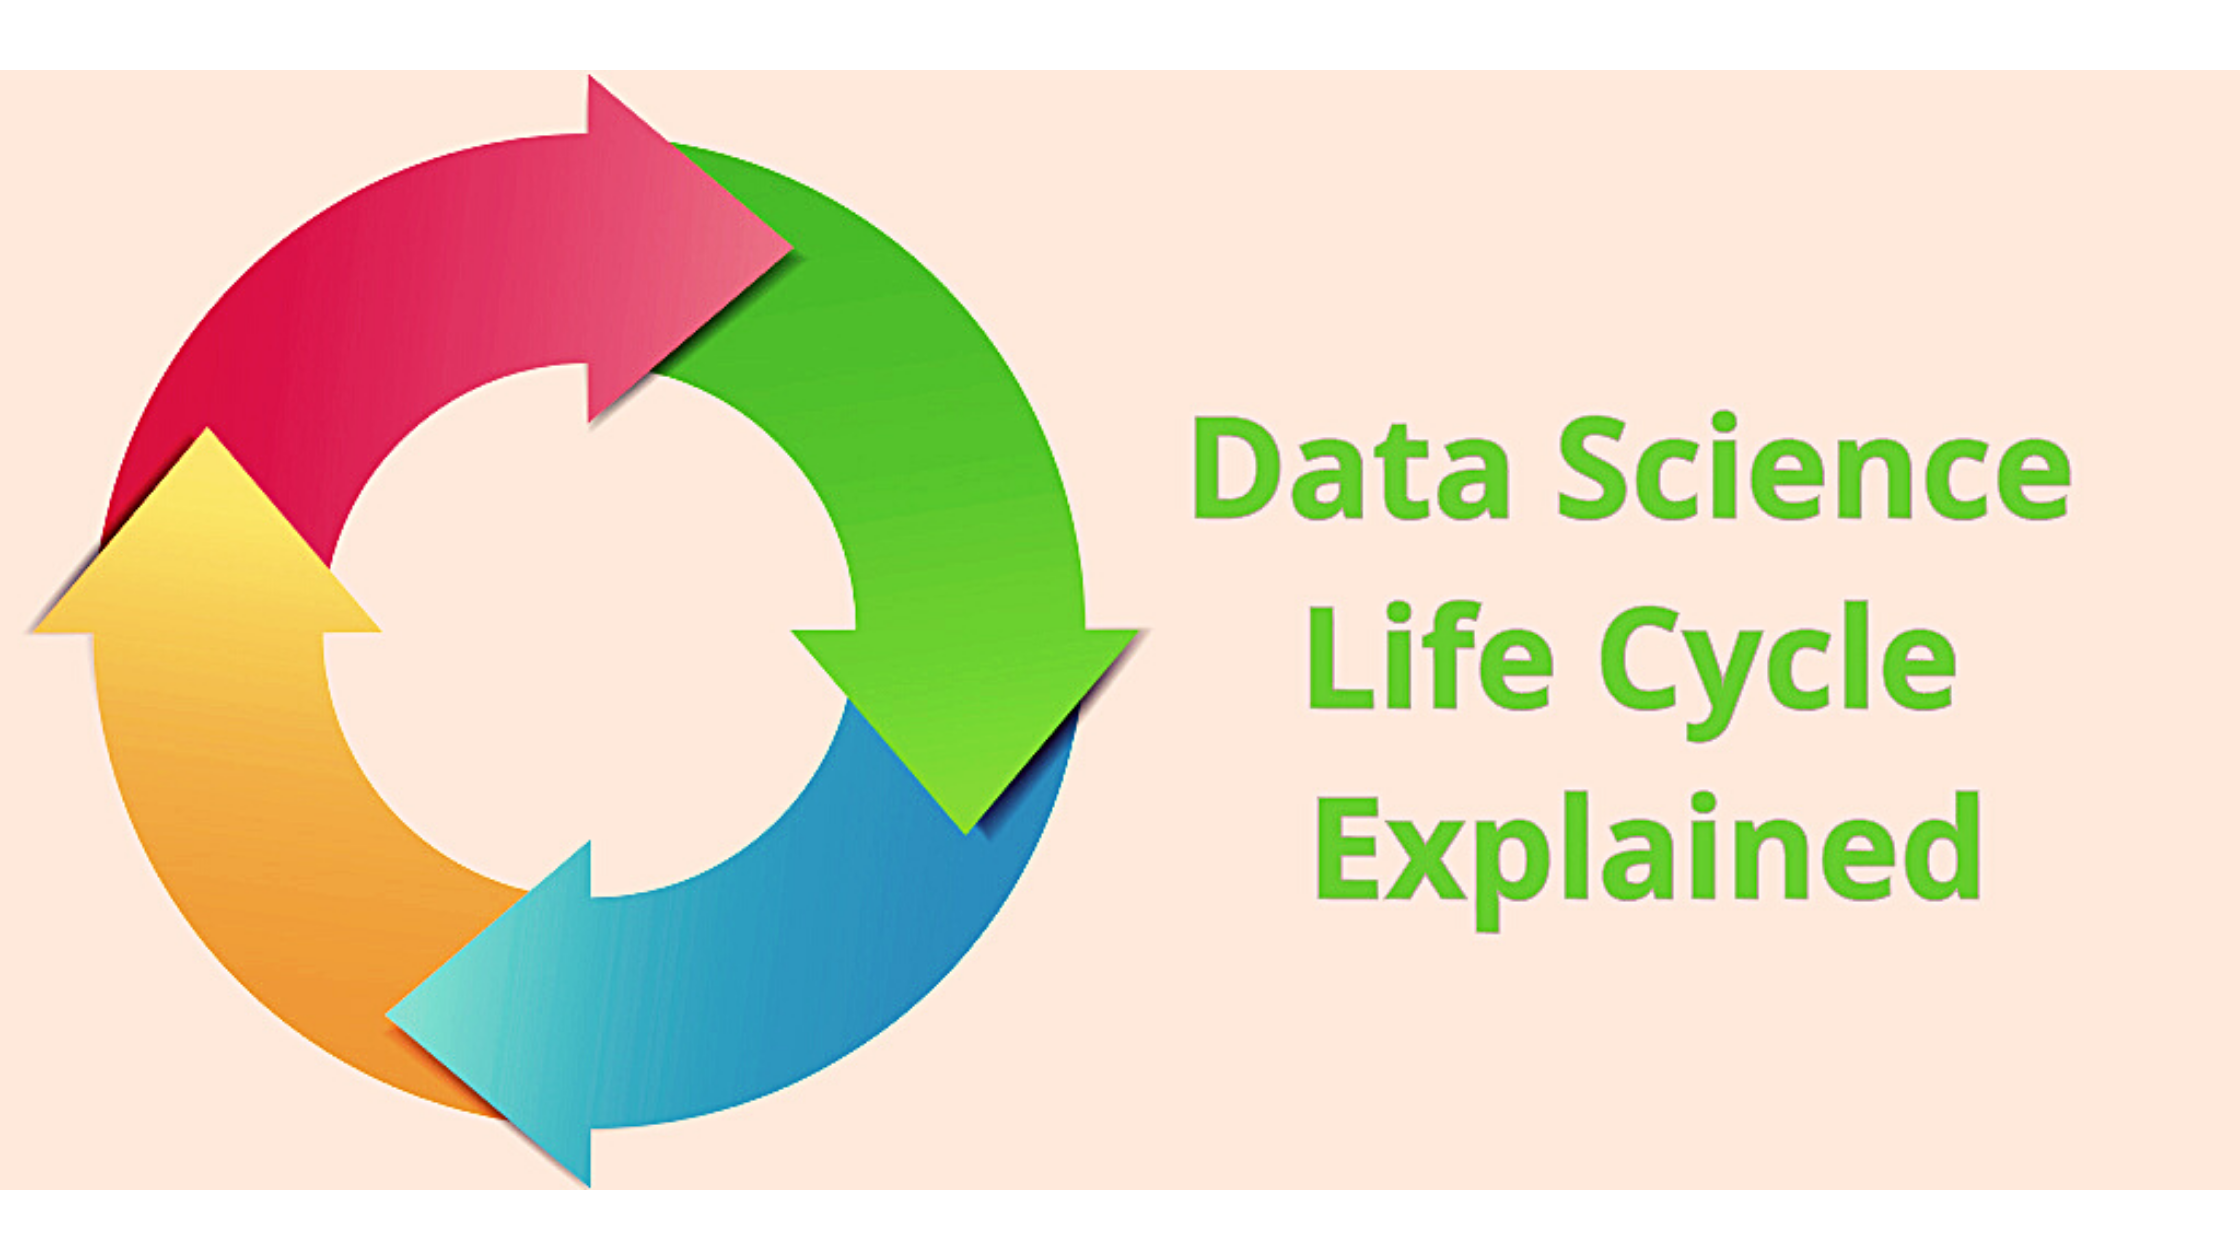
Data science and artificial intelligence (AI) have revolutionized the way businesses operate and make decisions. By leveraging vast amounts of data and advanced machine learning (ML) algorithms, organizations can uncover hidden patterns, make accurate predictions, and automate complex processes. However, successful data science projects require more than just technical skills – they demand a systematic approach that aligns with business goals and allows for continuous iteration and improvement.
In this in-depth guide, we‘ll explore the data science project lifecycle from the perspective of an experienced AI/ML practitioner. We‘ll delve into each phase of the process, highlight key considerations and best practices, and analyze real-world examples and trends. Whether you‘re a data science leader, an aspiring AI/ML engineer, or a business stakeholder looking to harness the power of data, this guide will provide you with a comprehensive roadmap for delivering successful data science projects.
The Rise of Data Science and AI/ML
Before diving into the lifecycle, let‘s set the stage by examining the rapid growth and impact of data science and AI/ML in recent years. According to the International Data Corporation (IDC), worldwide spending on AI systems is expected to reach $97.9 billion in 2023, more than double the amount spent in 2019 [^1]. This explosive growth is fueled by the increasing availability of data, advances in computing power and algorithms, and the proven ability of AI/ML to drive business outcomes.
Across industries, data science and AI/ML are being applied to a wide range of use cases, from customer churn prediction and fraud detection to supply chain optimization and drug discovery. A 2020 survey by McKinsey found that 50% of respondents had adopted AI in at least one business function, with the most common use cases being service operations optimization, AI-based enhancement of products, and contact center automation [^2].
The COVID-19 pandemic has further accelerated adoption of data science and AI/ML, as businesses seek to build resilience, adapt to new customer behaviors, and automate processes in the face of disruption. For example, healthcare providers have used AI to develop predictive models for disease progression and hospital capacity planning, while retailers have leveraged ML to optimize supply chains and personalize customer experiences.
Phases of the Data Science Project Lifecycle
With the context set, let‘s now explore each phase of the data science project lifecycle in detail.
Phase 1: Business Understanding
The foundation of any successful data science project is a deep understanding of the business problem at hand. This involves close collaboration with domain experts to define clear objectives, identify key performance indicators (KPIs), and assess the potential impact of the project.
Consider a retail company looking to reduce customer churn. The data science team would work with marketing and customer service stakeholders to define churn (e.g. customers who haven‘t made a purchase in the past 6 months), identify relevant data sources (e.g. purchase history, customer interactions), and establish KPIs (e.g. churn rate, customer lifetime value).
Techniques like design thinking and user story mapping can help ensure alignment between data science and business teams. The outcome of this phase should be a well-defined problem statement, a set of hypotheses to test, and a project charter that outlines scope, timeline, and resources.
Phase 2: Data Acquisition and Understanding
With the business objectives clearly defined, the next step is to acquire and understand the data needed for the project. This involves identifying relevant data sources, assessing data quality and availability, and integrating data from disparate systems.
In the customer churn example, data sources might include transactional databases, customer relationship management (CRM) systems, web analytics platforms, and social media feeds. The data team would need to evaluate the accuracy, completeness, and timeliness of each source, and develop a plan for extracting, transforming, and loading (ETL) the data into a centralized repository.
Exploratory data analysis (EDA) is a critical step in this phase, allowing data scientists to uncover patterns, anomalies, and relationships in the data. Techniques like data visualization, statistical analysis, and unsupervised learning can help generate insights and inform feature engineering.
According to a survey by Figure Eight, data scientists spend 60% of their time on data preparation tasks [^3], highlighting the importance of this phase. Automated data discovery and profiling tools can help accelerate the process, but domain expertise remains essential for interpreting results and ensuring data quality.
Phase 3: Data Preparation
Raw data is rarely ready for modeling without significant preprocessing. The data preparation phase involves cleaning, transforming, and feature engineering the data to optimize it for machine learning.
Common data preparation tasks include:
- Handling missing or incomplete data through techniques like imputation or deletion
- Dealing with outliers and anomalies using statistical methods or domain knowledge
- Transforming variables to normalize distributions or encode categorical data
- Feature scaling to ensure all variables are on a similar scale
- Creating new features through domain-specific transformations or aggregations
In the customer churn example, data preparation might involve imputing missing demographic data, encoding categorical variables like product categories or marketing channels, and creating new features like total lifetime spend or time since last purchase.
Data preparation is often the most time-consuming and iterative phase of the data science lifecycle. While automated tools can streamline the process, domain expertise is critical for making informed decisions and avoiding common pitfalls like data leakage or overfitting.
Phase 4: Modeling
With clean, prepared data in hand, the modeling phase involves selecting appropriate machine learning algorithms, training models on the data, and tuning hyperparameters to optimize performance. The choice of algorithm depends on the type of problem being solved (e.g. classification, regression, clustering), the size and structure of the data, and the desired output.
For the customer churn problem, a data scientist might start with a simple logistic regression model to establish a baseline, then experiment with more advanced algorithms like decision trees, random forests, or gradient boosting machines. Each model would be trained on a subset of the data and evaluated using metrics like accuracy, precision, recall, and F1 score.
Hyperparameter tuning is a critical step in optimizing model performance. Techniques like grid search and random search can help identify the best combination of parameters, while cross-validation ensures that models generalize well to new data.
Ensemble methods, which combine multiple models to improve predictive power, are another powerful technique used in this phase. For example, a stacking ensemble might combine the outputs of a decision tree, a random forest, and a neural network to produce a final prediction.
According to a recent survey by Kaggle, the most commonly used algorithms for structured data problems are gradient boosting machines (used by 75% of respondents), followed by random forests (73%) and logistic regression (72%) [^4]. Deep learning techniques like convolutional neural networks (CNNs) and recurrent neural networks (RNNs) are also gaining popularity, particularly for unstructured data problems like image and speech recognition.
Phase 5: Evaluation
Before deploying a model into production, it‘s essential to rigorously evaluate its performance and ensure it meets the defined business objectives. This involves assessing the model‘s accuracy, robustness, and generalizability using a variety of statistical and user-centric methods.
Common evaluation techniques include:
- Holdout validation: Testing the model on a subset of data that was not used for training
- Cross-validation: Repeatedly splitting the data into training and testing sets to assess model stability
- Confusion matrix: Visualizing the model‘s performance in terms of true positives, true negatives, false positives, and false negatives
- ROC curve: Plotting the model‘s true positive rate against its false positive rate to assess discrimination power
- Lift curve: Comparing the model‘s performance to a random baseline to quantify improvement
- User acceptance testing: Conducting qualitative assessments with business stakeholders to ensure the model meets their needs and expectations
In the customer churn example, the data science team would evaluate the final model‘s ability to accurately predict which customers are at risk of churning, and assess the business impact of targeting those customers with retention interventions. They might also conduct sensitivity analyses to understand how the model performs under different scenarios, such as changes in the economic environment or competitor activities.
Evaluation is an iterative process, and insights generated during this phase often inform further rounds of data preparation and modeling. It‘s important to involve business stakeholders throughout the evaluation process to ensure alignment and buy-in.
Phase 6: Deployment
The final phase of the data science lifecycle involves deploying the model into a production environment where it can generate insights and drive business actions. This requires close collaboration between data science, IT, and business teams to ensure a smooth integration with existing systems and processes.
Deployment typically involves the following steps:
- Model serialization: Saving the trained model in a format that can be easily loaded and used for prediction (e.g. pickle, PMML)
- Model serving: Deploying the model on a server or cloud platform that can handle incoming prediction requests (e.g. Flask, AWS SageMaker)
- Data pipeline: Establishing an automated data pipeline that feeds new data to the model for predictions (e.g. Airflow, Kafka)
- Monitoring: Setting up systems to monitor the model‘s performance over time and detect data drift or model decay (e.g. Prometheus, Grafana)
- Maintenance: Establishing processes for retraining and updating the model as new data becomes available or business requirements change
In the customer churn example, the final model might be deployed as a microservice on a cloud platform like AWS or Google Cloud, with a REST API that can be called by the marketing team‘s campaign management system. The data pipeline would continuously feed new customer data to the model, generating churn risk scores that trigger targeted retention interventions.
Model monitoring is critical to ensure the model continues to perform well over time. Techniques like statistical process control (SPC) and anomaly detection can help identify when the model‘s performance is degrading or the input data is changing in unexpected ways.
Trends and Future Directions
As data science and AI/ML continue to evolve, several key trends are shaping the field and the way projects are executed:
-
AutoML: Automated machine learning tools like H2O, DataRobot, and Google Cloud AutoML are making it easier for non-experts to build and deploy models, by automating tasks like feature engineering, model selection, and hyperparameter tuning.
-
MLOps: Machine Learning Operations (MLOps) is an emerging discipline that aims to streamline the deployment, monitoring, and maintenance of ML models in production. Tools like Kubeflow, MLflow, and TensorFlow Extended are helping teams collaborate and automate the ML lifecycle.
-
Explainable AI (XAI): As AI/ML models become more complex and opaque, there is growing demand for techniques that can explain how models make decisions and identify potential biases. Techniques like SHAP, LIME, and Grad-CAM are helping to improve model interpretability and transparency.
-
Transfer learning: Transfer learning involves leveraging pre-trained models and adapting them to new tasks or domains, reducing the need for large labeled datasets and accelerating model development. Techniques like fine-tuning and domain adaptation are making transfer learning more accessible and effective.
-
Reinforcement learning (RL): RL is a type of ML that involves training agents to make sequential decisions in an environment to maximize a reward signal. RL is being applied to a growing range of use cases, from robotics and autonomous vehicles to personalized recommendations and game playing.
Getting Started with Data Science and AI/ML
Embarking on a career in data science or AI/ML requires a combination of technical skills, domain knowledge, and business acumen. Here are some key steps to get started:
-
Build a strong foundation in mathematics, statistics, and programming. Courses in linear algebra, calculus, probability, and machine learning are essential, as are programming languages like Python, R, and SQL.
-
Gain practical experience through projects and competitions. Platforms like Kaggle, DrivenData, and Zindi offer a wide range of datasets and problems to practice on, as well as opportunities to collaborate with other data scientists.
-
Develop domain expertise in a specific industry or function. Understanding the business context and stakeholder needs is critical for delivering impactful data science projects.
-
Stay up to date with the latest tools and techniques. The field of data science and AI/ML is evolving rapidly, so continuous learning is essential. Follow industry blogs, attend conferences and webinars, and participate in online communities to stay on the cutting edge.
-
Build a portfolio of projects that showcase your skills and experience. A strong portfolio can help you stand out in the job market and demonstrate your ability to solve real-world problems with data.
Conclusion
The data science lifecycle provides a structured approach to solving business problems with data and AI/ML techniques. By following a systematic process of business understanding, data preparation, modeling, evaluation, and deployment, data science teams can deliver results that are both technically sound and aligned with business objectives.
However, the success of data science projects relies on more than just technical skills. Effective communication, collaboration, and domain expertise are equally important, as is a willingness to iterate and adapt as new insights emerge.
As data science and AI/ML continue to transform industries and shape the future of work, those who can master the lifecycle and deliver impactful projects will be in high demand. By staying curious, continuously learning, and focusing on delivering value to stakeholders, data scientists and AI/ML practitioners can help unlock the full potential of data-driven insights and decision making.
[^1]: IDC Worldwide Artificial Intelligence Systems Spending Guide, 2021[^2]: McKinsey State of AI in 2020 Survey, 2020
[^3]: Figure Eight Data Scientist Survey, 2018
[^4]: Kaggle State of Machine Learning and Data Science Survey, 2020