YOLOv7: Real-time Object Detection at its Best
Object detection is a fundamental task in computer vision that involves identifying and localizing objects of interest within an image or video stream. It has wide-ranging applications, from self-driving cars and robot perception to video surveillance and medical image analysis. While object detection has seen tremendous progress in recent years thanks to deep learning, performing this task accurately and efficiently in real-time remains an ongoing challenge.
Enter YOLOv7 – the latest and greatest incarnation of the famous YOLO (You Only Look Once) family of real-time object detectors. Released in 2023, YOLOv7 pushes the state-of-the-art in object detection by introducing novel architectural innovations that significantly boost speed and accuracy over its predecessors and other competing models. According to the YOLOv7 paper, this model achieves an impressive 56.8% Average Precision (AP) on the COCO benchmark at a real-time speed of 30 frames per second (FPS), outperforming top detectors like YOLOR, Scaled-YOLOv4, and even transformer-based models like SWINL Cascade Mask R-CNN.
So what makes YOLOv7 so special? Let‘s take a deep dive into its architecture to find out.
Inside the YOLOv7 Architecture
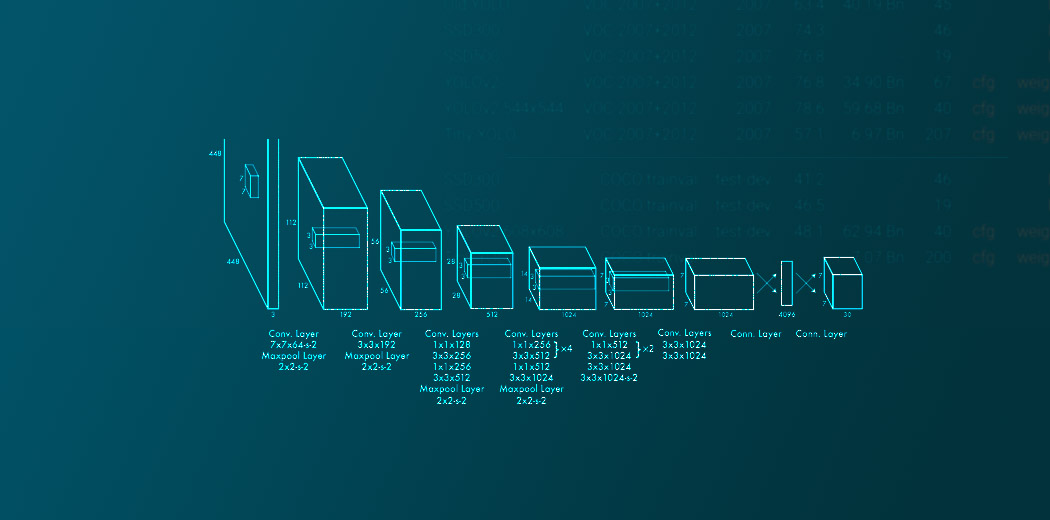
At its core, YOLOv7 builds upon the tried-and-true YOLO architecture that frames object detection as a regression problem. It divides the input image into a grid and predicts bounding boxes and class probabilities for each grid cell in a single forward pass. However, YOLOv7 introduces several key architectural innovations that take its performance to new heights:
Extended Efficient Layer Aggregation Network (E-ELAN)
E-ELAN is an optimization to the standard YOLO backbone that focuses on striking an optimal balance between model parameters and computational complexity. It extends the idea of layer aggregation from YOLOv6 by combining three techniques:
- Channel expansion via group convolution to increase model width
- Feature map shuffling to enable cross-group information flow
- Merging of the expanded feature maps to produce the final output
This allows E-ELAN to learn more diverse and expressive features without significantly inflating computation. The end result is a backbone that converges faster and generalizes better than previous designs.
Model Scaling for Concatenation-based Models
Another key aspect of YOLOv7 is its approach to model scaling, i.e., controlling model parameters to generate a family of models at different computation and accuracy levels. While most prior work has focused on scaling individual dimensions like depth or width, YOLOv7 proposes a compound scaling method tailored for concatenation-based models like YOLO.
The main insight is that simply scaling the depth of a concatenation-based network can lead to sub-optimal architectures, as it causes an imbalance between the input and output channels of the transition layers. To address this, YOLOv7 jointly scales the depth and width of the network using a two-step process:
- Scale the depth of each computational block in the network
- Scale the width of the transition layers to compensate for the change in output channels introduced by depth scaling
This compound scaling technique allows YOLOv7 to maintain optimal network structure at different model scales, from tiny to extra large variants.
Planned Re-parameterized Convolution
YOLOv7 also incorporates planned re-parameterized convolution, a modified version of the re-parameterization technique used in previous YOLOs to boost training efficiency. The idea is to replace certain convolutional layers in the network with a re-parameterized variant known as RepConv.
However, YOLOv7 takes this a step further by identifying that RepConv should not be applied to layers with residual or concatenation connections, as the identity mapping can negatively impact performance. Instead, it proposes RepConvN, a variant without the identity branch, for these layers. This improves optimization stability and leads to faster convergence.
Coarse-to-Fine Label Assignment
Finally, YOLOv7 introduces a novel label assignment strategy for guiding the learning of its detection heads. Most object detectors use a simple one-to-one label assignment, where each ground-truth box is matched to a single anchor box. YOLOv7 proposes a coarse-to-fine assignment that generates two sets of labels:
- Coarse labels that match a ground-truth box to multiple anchor boxes to provide more supervision
- Fine labels that match a ground-truth box to a single anchor box for precise localization
These label sets are dynamically mixed during training using a soft weighting scheme. The coarse labels are used to train an auxiliary detection head that guides the learning of the main lead head. This auxiliary-lead head structure, combined with the coarse-to-fine labels, significantly improves detection accuracy, especially for small objects.
YOLOv7 Performance
So how does YOLOv7 actually perform? To evaluate its speed and accuracy, the authors test YOLOv7 on the popular COCO benchmark, which contains 80 object categories over 330K images. They compare YOLOv7 against a wide range of state-of-the-art object detectors, from single-stage models like YOLOv5 and YOLOX to multi-stage models like Cascade R-CNN and Swin Transformer.
The results are impressive to say the least. On the COCO test set, YOLOv7 achieves 56.8% AP at a real-time speed of 30 FPS using an input resolution of 640×640 pixels. This significantly outperforms previous real-time detectors like YOLOX (55.0% AP) and YOLOv5 (51.2% AP). In fact, YOLOv7 even beats much slower and more complex transformer-based models like Swin-L Cascade Mask R-CNN (56.4% AP at 7.6 FPS).
Perhaps even more remarkable is YOLOv7‘s efficiency. The authors show that YOLOv7 is nearly 5x more efficient than Swin-L Cascade Mask R-CNN in terms of FLOPs per pixel (a measure of computational cost) at the same accuracy. This makes YOLOv7 highly suitable for resource-constrained settings like mobile or embedded devices.
The authors also test YOLOv7 on other tasks beyond object detection, such as instance segmentation and real-time object tracking. YOLOv7 achieves state-of-the-art results on these tasks as well, demonstrating its versatility as a general-purpose vision backbone.
Training and Deploying YOLOv7
Training YOLOv7 follows the standard paradigm for most deep learning object detectors. The authors provide detailed instructions and code for training YOLOv7 from scratch on a custom dataset, as well as for fine-tuning a pre-trained model on a new task. The key steps are:
-
Prepare the dataset by annotating images with bounding boxes and class labels. The authors recommend using a tool like LabelImg for this.
-
Convert the annotations to the YOLO format, which represents each bounding box by its center coordinates, width, and height relative to the image size.
-
Configure the model architecture, hyperparameters, and data augmentation settings in a YAML file. YOLOv7 provides a variety of pre-configured models that serve as good starting points.
-
Launch the training script, specifying the dataset, model configuration, and output directory. YOLOv7 uses mixed precision training by default to reduce memory usage and training time.
-
Evaluate the trained model on a validation set and select the checkpoint with the best performance. The authors provide an evaluation script that computes standard detection metrics like mAP.
For deployment, YOLOv7 can be easily integrated into different deep learning frameworks and environments. The authors provide pre-trained models and inference code for PyTorch, TensorFlow, and OpenCV. They also show how to optimize YOLOv7 for different deployment scenarios, such as using TensorRT for accelerated inference on NVIDIA GPUs or converting the model to TFLite format for efficient execution on mobile devices. This flexibility makes YOLOv7 accessible to a wide range of users and applications.
Applications of YOLOv7
Given its exceptional speed-accuracy tradeoff, YOLOv7 is well-suited for a variety of real-world applications that require real-time object detection. Some notable examples include:
-
Autonomous driving: YOLOv7 can be used to detect pedestrians, vehicles, traffic signs, and other obstacles in real-time from cameras mounted on self-driving cars. This enables the car to navigate safely and make quick decisions in dynamic environments.
-
Robotics: YOLOv7 can serve as the perception module for robots, allowing them to detect and interact with objects in their environment. This is crucial for tasks like grasping, manipulation, and navigation in warehouses, factories, and homes.
-
Video surveillance: YOLOv7 can be used to analyze live video feeds from security cameras to detect suspicious activities, track individuals, or count people/vehicles. This can help automate tasks like intrusion detection, crowd monitoring, and traffic management.
-
Medical imaging: YOLOv7 can be applied to medical images like X-rays, CT scans, and MRIs to detect abnormalities such as tumors, lesions, or fractures. This can assist radiologists in diagnosis and treatment planning.
-
Retail analytics: YOLOv7 can be used to analyze in-store camera feeds to track customer behavior, monitor inventory levels, or detect theft. This can provide valuable insights for optimizing store layout, product placement, and staffing.
Of course, this is just a small sample of the many possible applications of YOLOv7 and object detection in general. As the technology continues to advance, we can expect to see even more innovative uses emerge in the future.
Conclusion
In summary, YOLOv7 represents a significant milestone in the evolution of real-time object detection. By introducing novel architectural choices like E-ELAN, planned re-parameterized convolution, and a coarse-to-fine label assignment strategy, YOLOv7 achieves an unprecedented combination of speed and accuracy on benchmark datasets. Its efficient design also makes it highly suitable for deployment on resource-constrained edge devices.
Looking forward, there are still many exciting directions for improving YOLOv7 and object detection as a whole. One promising avenue is the integration of transformer architectures, which have shown impressive results on other vision tasks but remain challenging to apply in real-time settings. Another direction is the development of more robust and adaptive object detectors that can handle domain shifts and out-of-distribution data.
Ultimately, the goal is to build object detection systems that can match or even surpass human-level perception in terms of speed, accuracy, and generalization. With models like YOLOv7 pushing the boundaries of what‘s possible, we are well on our way to achieving that goal. So whether you‘re a computer vision researcher, a machine learning engineer, or just someone excited about the latest advances in AI, give YOLOv7 a try and see for yourself why it‘s real-time object detection at its best!
References
-
Wang, C., Bochkovskiy, A., & Liao, H. M. (2023). YOLOv7: Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors. arXiv preprint arXiv:2207.02696.
-
Bochkovskiy, A., Wang, C. Y., & Liao, H. M. (2020). YOLOv4: Optimal speed and accuracy of object detection. arXiv preprint arXiv:2004.10934.
-
Ge, Z., Liu, S., Wang, F., Li, Z., & Sun, J. (2021). YOLOX: Exceeding YOLO series in 2021. arXiv preprint arXiv:2107.08430.
-
Jocher, G. et al. (2021). YOLOv5. https://github.com/ultralytics/yolov5
-
Liu, Z., Lin, Y., Cao, Y., Hu, H., Wei, Y., Zhang, Z., … & Guo, B. (2021). Swin transformer: Hierarchical vision transformer using shifted windows. In Proceedings of the IEEE/CVF International Conference on Computer Vision (pp. 10012-10022).